I’m sure we’ve all been there - coat on, shoes on, just about to lock the door and - “did i leave the back window open?”
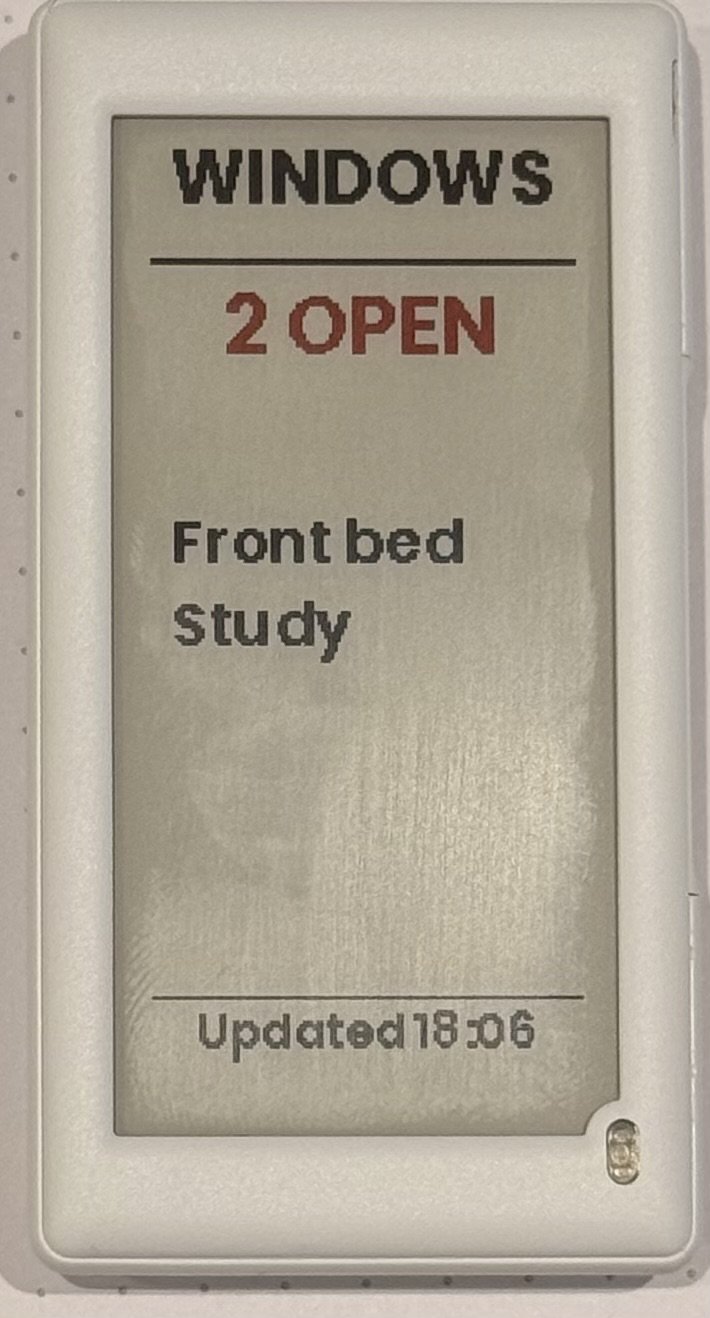
I wanted something which shows me, at a glance, which windows are open, or confirms they’re all closed.
goals
low maintenance - dont need to charge it every week
automatically updates in a few seconds
our windows can be “closed” or “latched closed” (with a ventilation space around), so support both
easy to glance at - no complex dashboards
small and unobtrusive.
What i used
Home Assistant Yellow
SNZB-04P/PR1 sensors
2.6" Hanshow Polaris Pro 280 Electronic Shelf Label
LilyGo T-Panel S3
OpenEPaperLink HA integration
Window sensors
I wanted sensors with long battery life. I have a Home Assistant Yellow at home, which has Zigbee support. I already have several Zigbee plugs around the house. Most permanently powered Zigbee devices act as “routers” so there’s a strong network around the house. I decided to buy Sonoff SNZB-04P:
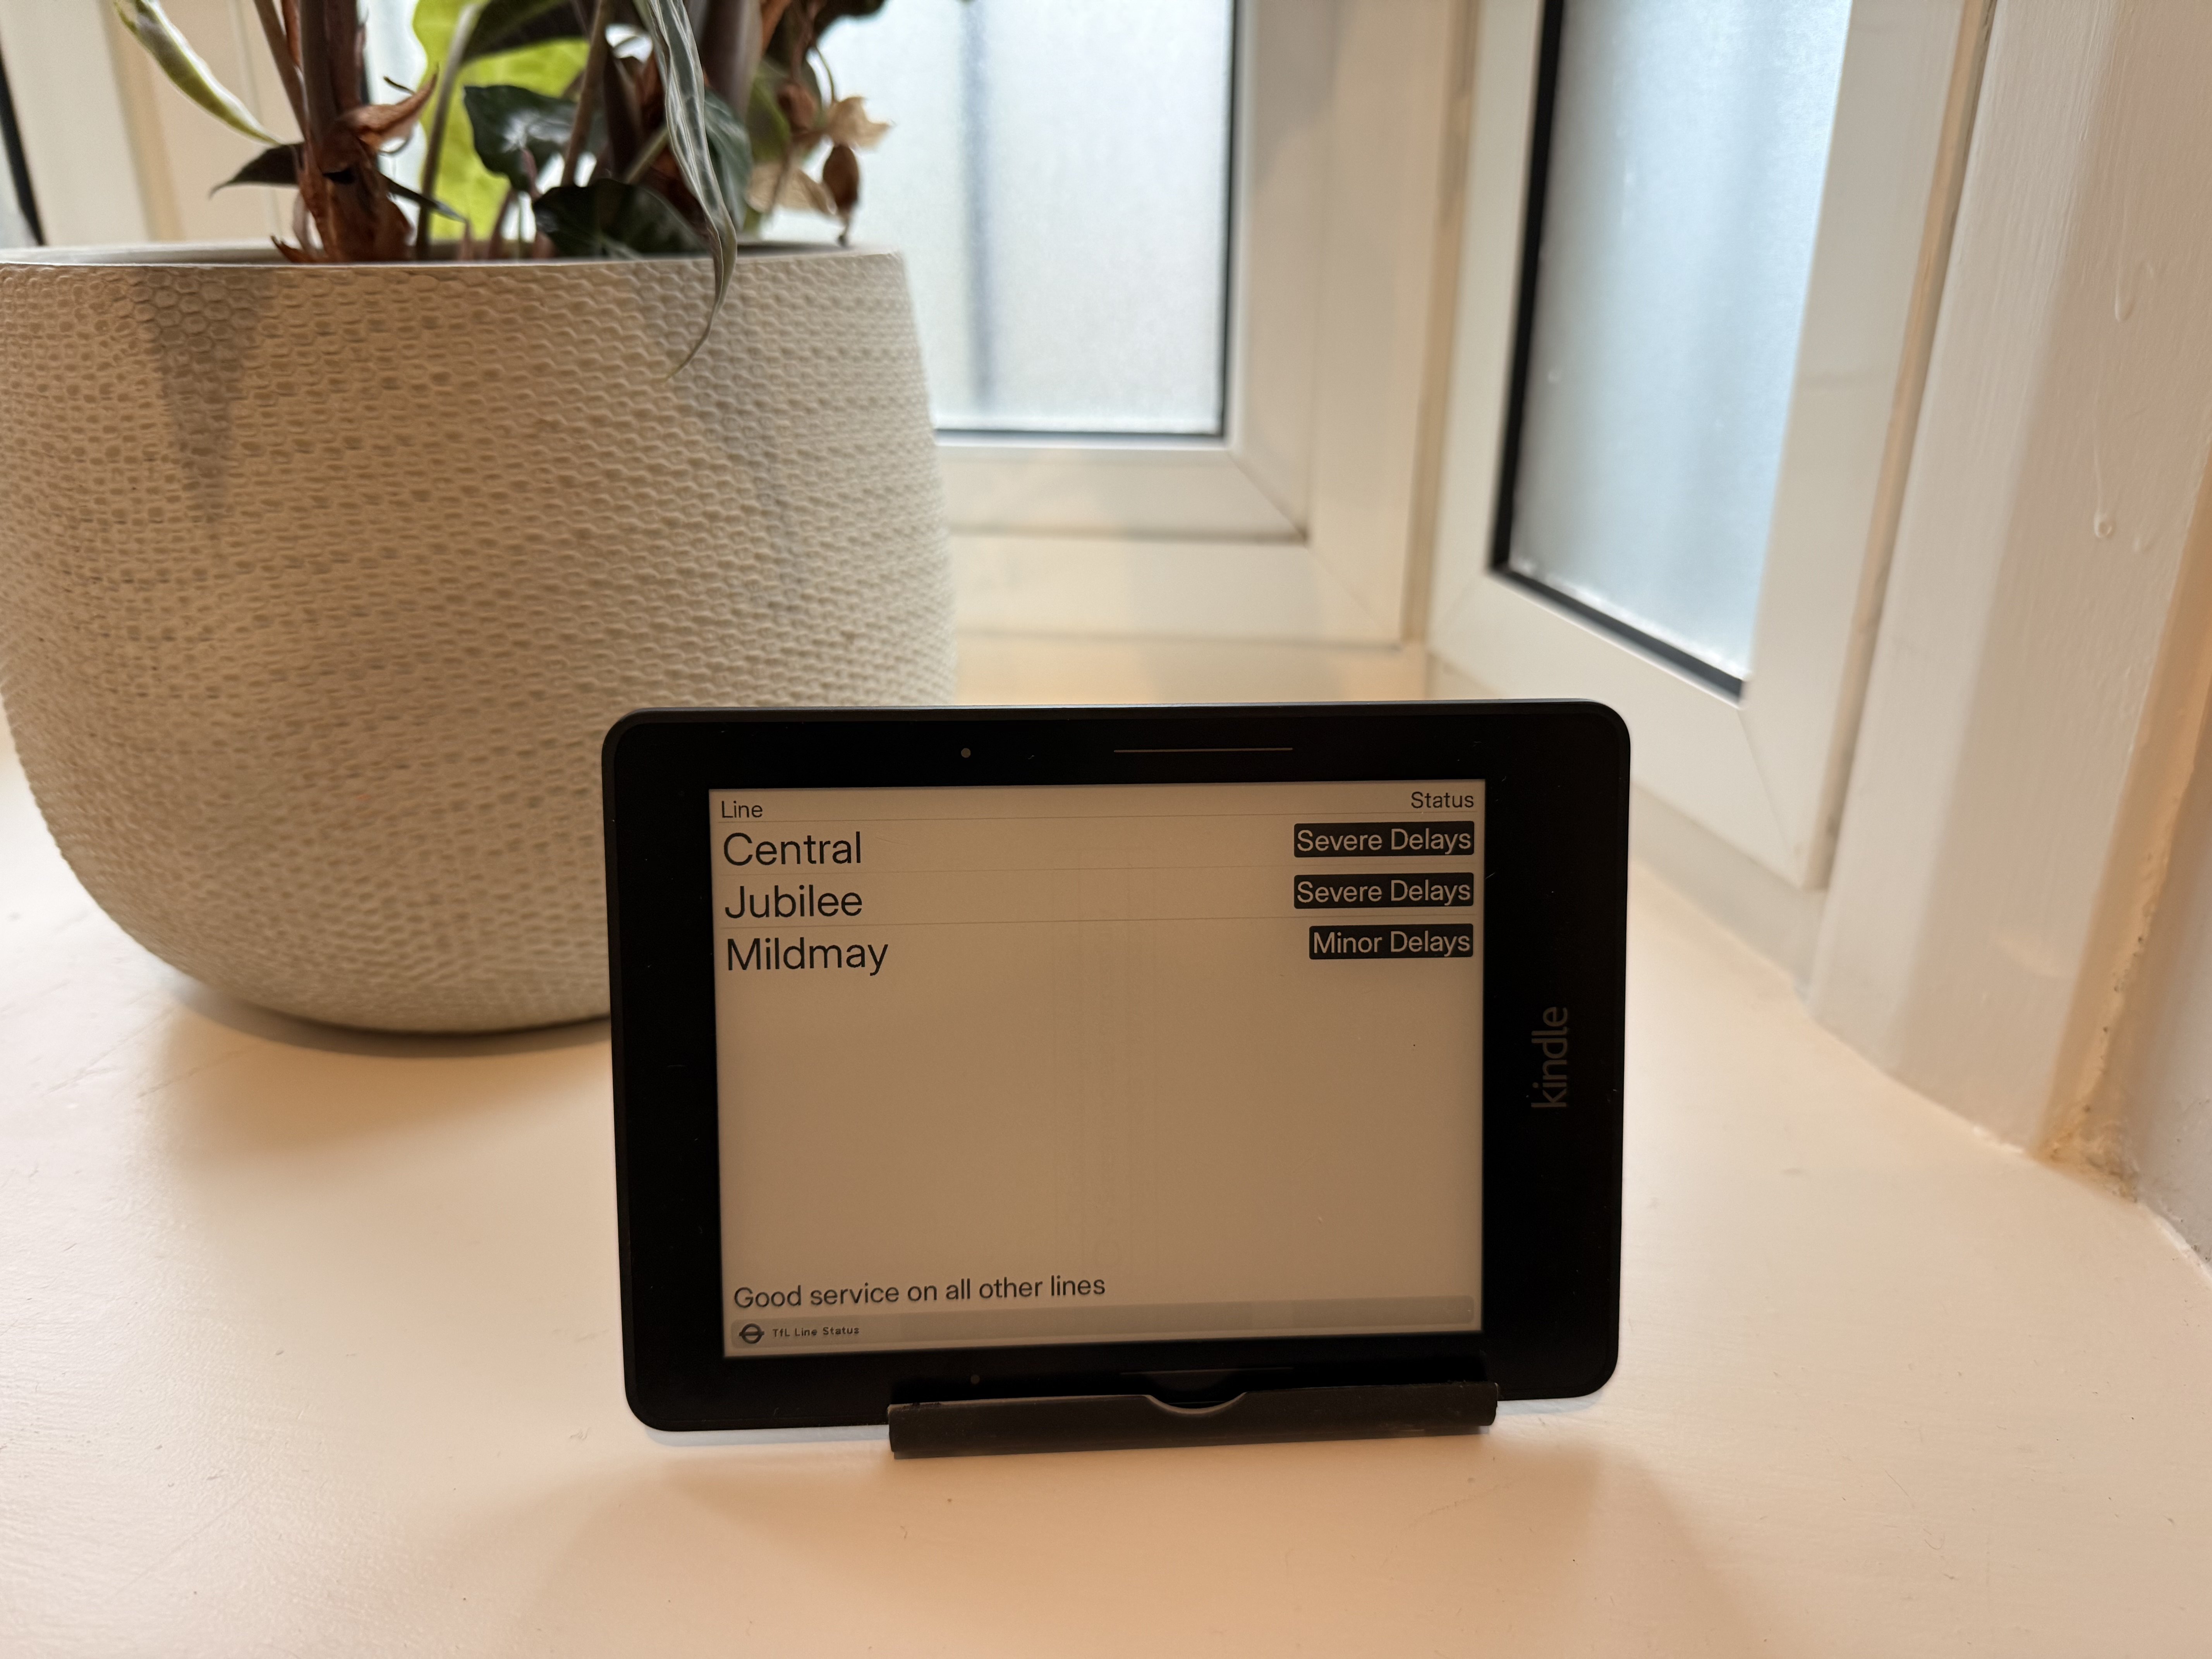
I’ve written before about TRMNL - it’s a great project. During a recent cleanout, i found an old Kindle Voyage in the back of a drawer. As well as supporting their own devices, TRMNL offers a “BYOD” licence and, if you manage to get it up and running on a device that nobody else has published before, they even give you back some of the licence fee!
TRMNL is an awesome open-source ePaper display that lets users show almost anything they want. Launched on Kickstarter, it’s now got thousands of plugins and users. I’ve published a few plugins myself. A few weeks ago, TRMNL added an MCP server. This lets you use a local coding agent to do most of the grunt work. I wrote about how to set that up in another post.
Secret disclosure
As soon as i’d set up the MCP server, i asked Claude to test it against a plugin i’d already built and deployed. The model called IntegrationsShowTool with no arguments. The response included:
TRMNL is an awesome open-source ePaper display that lets users show almost anything they want. Launched on Kickstarter, it’s now got thousands of plugins and users. I’ve published a few plugins, including a realtime TfL bus stop arrival time board.
A few weeks ago, TRMNL added an MCP server. This lets you use a local coding agent to do most of the grunt work.
Install the MCP server through .mcp.json
Using Claude Code, i created a simple .mcp.json file which references the API key by environment variable. Place this in the root of your repo. As it contains no secrets, this is safe to commit:
To stop my API keys being sucked up by some random malware, I keep secrets in 1Password and inject them into commands at runtime with op run. That works for almost everything, but when using Claude Code, i started getting a confusing error message.
Injecting MCP API keys to Claude Code
Claude Code reads MCP server config from .mcp.json and expands ${VAR} references from the environment.
gently (low temperature) fry onion in the vegetable oil for 5-6 mins over a medium heat in the small (metal?) roasting tin you’ll use in the smoker
Take off the heat and add the grated garlic
Add the beans and hendersons
Stir and put in the smoker (110-120c) for 60-90 minutes. Check after 60 mins to make sure not dried out. If it starts to get dry, add a splash of water. Stir.
Boil new potatoes until fork-tender (15-20 min) then drain
smash them on a sheet tray to break them slightly. The fluffy bits go crispy.
Coat them in oil/fat (e.g. drizzle in vegetable oil) and seasoning (salt, pepper)
roast in the oven at 220°C for 20-25 minutes until the edges are crispy and golden.
Transfer to the smoker at 110-130°C for 20-30 minutes to pick up smoke flavour. The already-crisped surfaces absorb smoke well. Going longer than 30 minutes risks drying them out or making the smoke flavour acrid.
I previously wrote about how i’d implemented a combination of 1Password’s CLI and direnv to avoid storing passwords on disk. This works great, most of the time. The problem comes when i want to add a secret and i’m in the middle of a complex multi-agent task - because the environment is loaded once before Claude or Codex or whatever starts, adding or rotating credentials during a build (e.g. if the agent needs an API key to a new service, or accidentally exposes a secret to its context) is tricky. So i’ve evolved the system slightly.
Recently at work, someone asked me why my team wasn’t creating detailed logical data models as part of their solution design. It seems quite simple to me – they don’t do it because nobody reads it. Most solution architecture documentation is out of date before it even gets logged in the architecture repository.
Why do we even write documentation?
I think we create documentation for one of two reasons:
Collaborate now: as soon as there is a second person in a team, they need to start talking so that they can work together. The more people, the harder this is (which is why we try to limit teams to half a dozen people or so). Documentation is a great way for people to collaborate. When things are written down, everyone can see it, and by adding comments or questions we get to a resolved version.
Communicate with the future: We make decisions today which are the best available given the information we have at the time. Sometimes we forget what we decided, or why, and documentation gives us that. It’s not about proving whether a decision was right or wrong – that’s largely irrelevant – it’s about understanding what led us to that decision in the first place. Perhaps the reasons are still valid and we just forgot what they were. Or perhaps information we have now changes things.
So really, design documentation is about ensuring that everyone’s on the same page, both now and in the future. Some designs are ephemeral – just to help us get our heads around what we want to do, and some is persistent – giving us a framework on which to hang our future plans.
separation of this vault from my main password vault in BitWarden. My whole world exists in Bitwarden - i dont want to inadvertently expose it. And as Bitwarden has a pretty awful CLI experience, it doesnt work for me.
Safe to commit secret file to source control
Safe to commit my .env files to source control because they no longer contain secrets
If you’re running Claude Code against your own API key or through a proxy instead of Anthropic’s native backend, you’ve probably noticed that the built-in WebSearch tool just doesn’t return results because it relies on a server-side API that only exists at Anthropic. Without web search, the agent cant research, so we built a self-hosted replacement using MCP.
What we built
The brilliant DDGS is an open source metasearch server that aggregates results from DuckDuckGo, Bing, Google, Brave, and Yahoo. It has a built in MCP server which exposes five tools: search_text, search_news, search_images, search_videos, and search_books.
Claude Code can do a lot of things. But can it keep a plant alive?
The Plant: Act I — Fifty-Eight Days
October 22 – December 19, 2025
On October 22, 2025, the moisture sensor read 1829, the first of 5,568 check-ins over fifty-eight days. The scale runs from wet at roughly 1100 to dry at 3400, putting that reading in the middle.
The sensor is in the pot of a Tradescantia zebrina. There’s also a 5l jug of water with a pump, a grow light and a camera. Claude’s job is to keep the plant alive - basically, keep the moisture in range and run the grow light on schedule, writing notes after each cycle so it could pick up where it left off. At the start, there were five unknowns: plant species, target moisture range, soil type, ambient temperature, and pot size. Claude logged all five, ran a 60-minute grow light session, and began monitoring. The full session logs, sensor data, and photos are at plants.cynexia.com if you want to follow along.
I have a personal GitHub account and a corporate one, and I found it annoying to have to select the correct SSH key for work repos, so I configured git and SSH to pick the correct key for me. After initial setup, there are three config files to modify:
After the initial setup, there are three config files involved:
Git URL rewrite (~/.gitconfig) — rewrites work org URLs to an SSH host alias
SSH host alias (~/.ssh/config) — maps that alias to the right key (and port 443 if needed)
Work-only Git identity (~/.gitconfig.work) — sets work email/name/signing key, loaded automatically for work repos
By default, Kafka attempts to send records as soon as possible, sending up to max.in.flight.requests.per.connection messages per connection. If you attempt to send more than this, the producer will start batching messages, but ultimately if you saturate the connection so there are unacknowledged message batches pending, the producer enters blocking mode.
We can optimise the way the producer batches messages to achieve higher throughput through two settings, batch.size and linger.ms.
linger.ms is the number of milliseconds that the producer waits for more messages before sending a batch. By default, this value is 0, meaning that the producer attempts to send messages immediately. Smaller batches have higher overhead - they are less compressible, and there’s an overhead associated with processing and acknowledging them. Under moderate load, messages may not come frequent enough to fill a batch immediately, but by introducing a small delay (e.g. 50ms), we can increase the likelihood that the producer can batch more messages together, improving throughput.
Claude Code is pretty amazing. It’s let me build prototypes and improve apps faster than I ever thought possible. But I was wondering - what else can it do?
I’ve been using Emby for years, but recently I started to wonder what happened to Jellyfin, the project that forked Emby years ago. So i decided to ask Claude Code to help me by setting up a debate and mediating the answer.
Although builds were succeeding locally, during CI builds were failing on Linux with the error Error: Cannot find module @rollup/rollup-linux-x64-gnu. npm has a bug related to optional dependencies. The log suggested removing package-lock.json - but this obviously breaks deterministic builds.
The root cause is a missing dependency - specifically, when Rollup needs native binaries for performance optimisation. Mac-generated lockfiles won’t include Linux-specific optional dependencies. First noted in npm bug 4828, it was fixed in npm 11.3.0+, but adding an explicit optional dependency prevents edge cases.
I was recently asked to design a method to meet ITAC (IT Application Controls) standards for critical data flows in our organisation. ITAC are application-level controls looking mainly at how we ensure the completeness, accuracy and validity of transactions - for example, invoices or trades. Our control set is based on the ICFR principles, of which ITAC is one part.
The specific control objective I was asked to look at relates to the risk of loss of integrity of financial data transfers. The focus on the integrity of the data, not authenticity or non-repudiation is really important as it means cryptographic solutions aren’t required - Kafka’s native protocol features can satisfy the requirements.
In a previous post, I explained how to configure Azurite to use a self-signed certificate to enable OAuth authentication. One challenge with this method is that the Azure Python SDK will refuse to connect to azurite, reporting errors such as:
azure.core.exceptions.ServiceRequestError: [SSL: CERTIFICATE_VERIFY_FAILED] certificate verify failed: unable to get local issuer certificate (_ssl.c:1006)
This is because the the Azure SDK uses the Requests library, which in turn uses Certifi as its source of root certificates. Certifi provides a regularly updated bundle of the Mozilla root trust store, and our self-signed custom certificate obviously isn’t in Mozilla’s trust list!
I’ve been using Azurite to simulate Azure storage for my development. If you’re not familiar with it, Azurite is a local storage emulator for Azure Storage, and you can read my other post about how i’ve set up my devcontainer configuration to run Azurite as a service container. As my deployed code is using an Azure Managed Identity, I wanted ensure my development environment was consistent with this and also uses Azure DefaultAzureCredential credential provider class. In this post, i will talk through the steps required to switch from using a connection string (with a well-known account and key) to using OAuth and HTTPS, helping to increase feature parity between development and production, reducing the chances of mistakes.
When developing with Azure Storage, it can significantly speed up your development process if you can use a local development environment, rather than constantly connecting directly to storage in Azure itself. This is where Azurite comes in - Azurite is a local storage emulator for Azure Storage, mimicing blob/container, queue and table storage. While there are lots of ways to get it running (e.g. from binary, manually using Docker etc.), I wanted to set it up as a service container in my devcontainer configuration which provides a few benefits:
In Pulumi, when calling pulumi_azure_native.storage.list_storage_account_service_sas_output() to generate a SAS, you pass the required permissions to the permissions: Input[str | Permissions | None] parameter. pulumi_azure_native.storage.Permissions is an enum, offering simple selections (R, L etc.):
But you can also pass a string of permissions, any of R, L, D, W, C, A, or P, depending on the actions you want to allow for the SAS. This allows you to specify permissions for reading (R), listing (L), deleting (D), writing (W), creating (C), adding (A), or processing (P) blobs within the container, such as permissions="RWL":
Another note for myself. I wanted to use this to give my app access to the entire account. I thought they would be a property of pulumi_azure_native.storage.StorageAccount but they’re not. Instead you need to call pulumi_azure_native.storage.list_storage_account_keys().
In a storage account, you can create a SAS scoped to a specific container, however, that SAS does not have permission to execute BlobClient.exists() as this requires at least list privileges on the parent object (e.g. the account), and when you try to perform the check, you’ll get this error:
azure.core.exceptions.HttpResponseError: This request is not authorized to perform this operation.
Note that this is an HttpResponseError, not a ClientAuthenticationError (which is actually a more specific error which extends HttpResponseError), so you need to interrogate the specific response code, although note that if the container client does not exist, you might also get a ClientAuthenticationError with this message:
This post is mainly a reminder to myself, because i’ve made the same mistake a few times in different projects.
How and why to deploy Azure functions from a package
When using Azure Functions, you can simplify deployment and maintenance of your function by deploying from a package file rather than directly in to the function. This also has the benefit of reducing cold start times, particularly where there are a large number of dependencies.
If you run in a dedicated mode, you need to turn on the Always On setting for your Function App to run properly … When running in a Consumption Plan or Premium Plan you should not enable Always On.
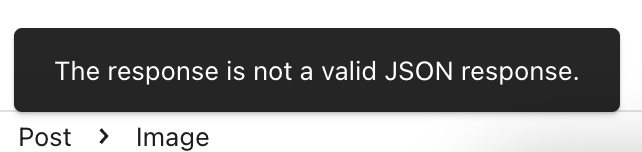
When uploading images to Wordpress, you may get this error. There are plenty of blogs online offering solutions, but they only apply to self-hosted instances - mine is hosted on just-what-i-find.onyx-sites.io/.
The error is a little pop up with the text The response is not a valid JSON response at the bottom of the screen when you try and upload an image:
In a previous post, I created a Barman backup script to back up PostgreSQL running in an VM to AWS S3. If you host your PostgreSQL server in Azure, this can get expensive quickly because you pay egress bandwidth fees to Microsoft. In this article, i’ll show you how to use Azure Blob storage instead.
Step 1: Install Barman, barman-cli-cloud, snappy etc.
Run these on both the source and target. Obviously, if you dont have the source any more (which is why you’re restoring), you’ll need to make some assumptions…
After a bit of playing around, I decided to use Barman for the backups - it’s significantly easier to configure and use than pgBackRest and has native support for backing up to S3, point-in-time restore, and more. The major downside compared to, say, running pg_dump every night, is that it requires an identical setup to restore to - identical hardware and PostgreSQL version. Least privileges in the database is tricky - to be able to back up things like roles, the account basically needs full access to all schemas. The Barman documentation says that it should run as the same user as PostgresQL, postgres.
I’ve been using timescale.com for about a year, but it’s quite expensive for a hobbyist (their cheapest plan in the UK is about $50/month), so I thought i’d try and implement something cheaper. I know i won’t get the cool automatic DR failover or the sexy continuous backups - but it’s not really mission critical if i lose a small amount of the history of my home energy consumption. Timescale publish some instructions, but they weren’t complete, and didnt work for me.
The Aggregation of Marginal Gains is an improvement model attributed to Dave Brailsford. When he took over as the head of British Cycling in 2002, the team was near the bottom of the rankings. Brailsford’s approach was to look at their processes in tiny detail, and improve each part by 1%, the logic being that these would all add up to a significant improvement. He talks about shipping mattresses between hotels so that athletes get a better nights’ sleep, or fastidiously cleaning the team truck to prevent dust and debris undermining the fine tuning of the bikes. And it was a success - in the 2008 and 2012 olympics, the team won 70% of the gold medals for track cycling.
When running apt-get update i was seeing these errors:
W: http://security.ubuntu.com/ubuntu/dists/jammy-security/InRelease: The key(s) in the keyring /etc/apt/trusted.gpg.d/postgres.gpg are ignored as the file is not readable by user '_apt' executing apt-key.
W: https://packagecloud.io/timescale/timescaledb/ubuntu/dists/jammy/InRelease: Key is stored in legacy trusted.gpg keyring (/etc/apt/trusted.gpg), see the DEPRECATION section in apt-key(8) for details.
Although the warning is annoying, it doesn’t stop things updating. I understand the reasons why the legacy keyring is being removed.
I love using devcontainers to manage my development environment. They make it super easy to ensure a consistent development stack is in place. Recently i started developing against a MongoDB instance. For node.js, i use mongodb-unit to spin up a standalone server on the local client. But there’s no equivalent package for Python.
Although there are lots of posts on stackoverflow about configuring a single node replicaset using a healthcheck, and there’s even an example given by a MongoDB employee, they didnt work for me. When setting up the server to use authentication, it also needs a keyfile, which has to be generated and secured in a specific way or you get this error:
I’ve previously explained the RICE and ICE techniques for prioritisation. Both techniques are frameworks used to evaluate and rank projects or tasks based on their potential impact, feasibility, and difficulty. However, I wanted to highlight the two key differences between them to help you chose the right tool for your project.
The ICE technique (Impact, Confidence, Ease) assigns scores to each project based on the potential impact of the project, the level of confidence in its success, and the ease of implementing it. The scores for each factor are multiplied to get a final score, which is used to rank the projects in order of priority.
Yesterday, i talked about the RICE technique for prioritisation. Today, i want to introduce ICE technique, another prioritisation framework used to evaluate and prioritise tasks or projects based on three factors: Impact, Confidence, and Ease. Tomorrow, i’ll compare them both.
Impact refers to the potential positive outcome or benefit of completing a particular task or project, considering the potential impact of the task or project on the overall goals or objectives of the organisation or project. For example, is this going to reduce costs? Increase customer loyalty or satisfaction? Reduce developer frustration?
Confidence refers to the level of certainty or confidence that the task or project will be successful - factors such as available resources, expertise, and potential roadblocks or obstacles. Are we likely to be able to deliver?
Ease refers to the level of difficulty or complexity of completing the task or project, taking account of things like the level of effort required, the time needed, the necessary skills needed, or difficulty obtaining or using resources. Perhaps the project isn’t that hard - but we simply don’t have a developer with the right skills to implement it, or perhaps we can’t support it/keep it running over time.
To use the ICE technique, each item is assigned a score out of 10 for each factor, and the scores are then multiplied together to calculate a final score for each task or project. The higher the final score, the higher we should prioritise completing that item.
Imagine that you are a product manager at a software company, and you have three potential features to prioritise for the next development cycle. How do you pick between them? There are many ways, but one i recently learned about is the RICE model - a prioritisation framework used by product managers, teams, and organisations to prioritise projects, features, or tasks based on their potential impact, effort, and other factors. RICE stands for Reach, Impact, Confidence, and Effort, and it provides a quantitative approach to decision-making.
In our world, we organise in Pods - an autonomous group of 6-9 people with all the skills needed to solve a problem. Multiple Pods form a Team. Within a Pod, there can be multiple Senior Developers, but only a single Lead Developer. They have different and overlapping responsibilities and accountabilities.
Every project must have exactly one Lead Developer, and has one or more Senior Developers.
It is the accountability of the project or product manager to ensure that these roles exist in a team, and that the roles are filled with skilled team members able and willing to fulfil the role.
We’ve recently been rolling out a new internal application. At our organisation, users have an email address which is generally firstname.lastname@company.com, or something like that. When a user logs in to the application, the app will look them up using their email address and figure out what parts of the application the user should be able to use.
The problem
One day we got a ticket for a user who was adamant that they had access but when we looked in the application, we couldn’t even find them in the system! Probing a bit further, it turns out that they had recently changed their name, and as a result, their email had changed.
When i think back to the deepest of the many deep holes i’ve dug myself in to over the years, they almost all start with an email.
When working through my inbox, it’s all too easy to just bash out a reply and hit send. Usually, that’s fine - a quick email is all it takes, and the issue is closed. But sometimes, that email triggers a reply, and that reply another, and it’s hard to predict when but eventually I’m having a complex conversation about a complex issue and it all goes wrong and before I know it, we’re at loggerheads and 37 people on the CC list think I’m a jerk.
This is an update of my previous post, now that cert-manager is more mature, and i’ve rebuilt my server on Ubuntu 20.04 (from 18.04).
install certbot
install script to update unifi certificate
Test
Issue full certificate
Install cron jobs to automate renewal
Install certbot
Certbot installation instructions are at online of course but here’s a summary:
Update package list: sudo apt update
install: sudo apt install -y certbot
Create a new certificate using LetsEncrypt
We’re going to use standalone mode, and first we’ll get a test certificate just to validate that everything’s working (so that we don’t trigger LetsEncrypt’s rate limits).
Generally when evaluating someone for a role, I look for 5 things:
Behaviours - how do they operate in a team? Do they admit to mistakes and learn from them? Do they help others? Communicate and live to their personal values? Are those values ones I want people in the team to live to?
Accountability - can this person handle the magnitude of the role? Are they able to manage stakeholders of the right level of seniority?
Domain - how deep is their knowledge of this business, industry, sector etc.? And how deep does it need to be?
Function - what is their level of skill in this type of role? For example, if hiring a business analyst, how good a business analyst are they?
Organisation - perhaps summarised as “knowing how things are done around here” - processes, culture etc. - does this person have the knowledge to make things happen?
Obviously, number 1 is a given - no one wants a brilliant jerk on the team. But most people have some of each of the others. The question is whether it’s enough to set them up for success in the new role. Usually, I’d expect someone to have strength in 1 or 2 of the others, and to have one or at most two which give headroom to grow as:
I often have conversations with friends and colleagues about their careers. And many times, i point people to a great blog post by my colleague Liz Aab, about the “7 Ps”. But i always find myself adding two to the list, so i thought i’d just post it here.
There are lots of factors which go in to choosing a job. You can’t have all of them, all of the time. At least, i think you can’t. But you can (and should) decide which are most important to you. Here are Liz’s 7 Ps (which she says were originally 5 Ps from some other source). I’ve added my two on the end, and i’ve reworded some of Liz’s original post:
Some repos, such a the one for the Unifi Controller, use different ‘field’ values to tie a release and require manual updates. For someone like me who has a standalone, automated controller setup designed mainly to keep the firmware up to date without much intervention, this is a hassle. It looks something like this:
robert@unifi:~$ sudo apt-get update
[sudo] password for robert:
Hit:1 http://mirrors.linode.com/ubuntu bionic InRelease
Get:2 http://mirrors.linode.com/ubuntu bionic-updates InRelease [88.7 kB]
Get:3 http://security.ubuntu.com/ubuntu bionic-security InRelease [88.7 kB]
Get:4 http://mirrors.linode.com/ubuntu bionic-backports InRelease [74.6 kB]
Ign:5 http://repo.mongodb.org/apt/ubuntu xenial/mongodb-org/3.4 InRelease
Hit:6 http://repo.mongodb.org/apt/ubuntu xenial/mongodb-org/3.4 Release
Get:7 https://dl.ubnt.com/unifi/debian stable InRelease [3,024 B]
Reading package lists... Done
E: Repository 'https://dl.ubnt.com/unifi/debian stable InRelease' changed its 'Codename' value from 'unifi-5.12' to 'unifi-5.13'
N: This must be accepted explicitly before updates for this repository can be applied. See apt-secure(8) manpage for details.
It’s an easy fix. Just tell apt-get to ignore the codename field:
The ZFS Pool on my server was showing degraded state. After checking the SMART status of the constituent drives and finding no problem, I discovered that there’s a bug in Solaris 10.5 where the system reports a growing number of errors and eventually fails the pool. dmesg shows an error unable to kmem_alloc enough memory for scatter/gather list, however, there is actually nothing wrong with the pool. Running zpool status shows degraded state:
For various reasons, not least because I wanted to play with it, we have a Yale Keyless Connected Smart Door Lock with a Z-Wave module (we have the v1 module which works fine). This lock has a couple of key features that we liked:
You can grant or revoke access using RFID tags or cards, or by entering a 6-8 digit code on the keypad.
With the Z-Wave module (and a compatible Z-Wave controller), you can programatically add and remove codes so that you can enable codes at specific time or dates. For us, this meant we could create a code for the cleaner, but if they turned up at 2am on a Saturday, the door wouldn’t open for them.
It’s connected to our Samsung SmartThings hub, and i run the RBoy Apps custom device type and smart app to enable the scheduled key rotation etc. Overall, we’ve been fairly happy with it, but the thing really does eat up batteries, and I started to feel guilty about putting between 4 or 8 AA batteries in the bin each month. Of course I also got annoyed at constantly having to buy them and change them, so I decided to try rechargeables.
Daniel Rausch, Amazon’s Vice President of Smart Home, reveals that it took 3 years to get to 4,000 Alexa-compatible devices on the market, but in the past 9 months that number has risen from 9,000 to 20,000, helped in no small part by Amazon’s efforts to simplify OEM vendor adoption through SDKs, hardware development training, supply chain options and more. So where does Amazon see this ending up? “The sky’s the limit … you will also see that Alexa will just be embedded in more devices and customers will stop thinking about talking to a device per se. It will become more about speaking at large.” https://www.techradar.com/news/amazon-soon-we-wont-talk-about-the-smart-home-but-a-world-of-smartsHome isn’t just where the smart is
Sometimes the code i write doesn’t work 6 months later - so I was incredibly impressed to read about the NASA team who reprogrammed the Voyager 1 space probe some 37 YEARS after the code was last changed. I can’t imagine what the 40 hour wait between sending the commands and receiving the response was like. https://www.nasa.gov/feature/jpl/voyager-1-fires-up-thrusters-after-37The Voyager team is able to use a set of four backup thrusters, dormant since 1980, for orienting the spacecraft.
Although we’re all used to resetting our smartphones before we sell them, I have to admit that i often forget to wipe the memory of the carplay-enabled hire cars I used over the summer before returning them to the hire company. The Register highlights growing concern among a range of stakeholders - but not car manufacturers - around the privacy and security implications of my forgetful behaviour. https://www.theregister.co.uk/2018/09/07/connected_cars_privacy/Manufacturers seem reluctant to do anything about it
In their 2018 Salary Survey, Stack Overflow reveals a global increase in Software Engineer salaries, with some locations like London and San Francisco seeing rises in median salary of around 25%, with DevOps engineers commanding the highest pay. Check out how your salary compares here - https://stackoverflow.com/jobs/salary - and read the explanatory blog here: https://stackoverflow.blog/2018/09/05/developer-salaries-in-2018-updating-the-stack-overflow-salary-calculator/Today we launched the 2018 update to the Stack Overflow Salary Calculator, a tool that allows developers and employers to find typical salaries for the software industry based on experience level,…
In a push to increase collaboration between the UK and Canada on industrial uses of AI, the UK government has teamed up with Canadian aircraft manufacturer Bombardier to offer a prize for ideas which solve an interesting problem - an optimal, self managing de-icing strategy for aircraft. De-icing causes extra fuel burn - either to carry the weight of ice-melting fluids, or to power heating elements at key points on the plane. Also, deicing at the wrong time can lead to other risks - such as ice forming in places not protected by countermeasures. £100k is up for grabs. https://www.theregister.co.uk/2018/09/07/ice_ice_baby_airliner_ai/Stop, collaborate and listen: Ice is back we need a brand new invention
In what must have been a fun project, creative agency redpepper has built a robot which can play Where’s Wally (Waldo in the US) using Google’s AutoML Machine vision service. https://www.youtube.com/watch?v=-i7HMPpxB-YWe built a little robot called “There’s Waldo” to test the capabilities of Google’s new AutoML Vision service. We’ve found that technologies can be unapproac…
As more and more teams work with the Arcade Learning Environment to train RL models on Atari games, it becomes more important to a) ensure that comparisons are truly like-for-like and reproducible, and b) find ways to speed up and simplify model iteration. Google has developed a Tensorflow framework, called Dopamine, allowing researchers to focus on the content of their tests and code, rather than spending time iterating and tweaking. https://ai.googleblog.com/2018/08/introducing-new-framework-for-flexible.htmlPosted by Pablo Samuel Castro, Research Software Developer and Marc G. Bellemare, Research Scientist, Google Brain Team Reinforcement lear…
One problem with existing training methods for unsupervised learning used in human language translation is the availability of text “pairs” (such as the same sentence written twice) between obscure languages - such as Welsh to Urdu. Facebook is testing out a new mechanism involving “word embeddings” - vector-space representation of words in a given language (e.g. kitty -> cat is closer than kitty -> rocket). Using this model, the relative positions of words can be used to create the translation between languages for which there is little existing identical material. Although promising, performance is still lower than using supervised methods. https://code.fb.com/ai-research/unsupervised-machine-translation-a-novel-approach-to-provide-fast-accurate-translations-for-more-languages/Automatic language translation is important to Facebook as a way to allow the billions of people who use our services to connect and communicate in their preferred language. To do this well, curren…
Looking for a way to pick up Python? Georgia Institute of Technology recently launched Code Shrew, a free, web-based learning platform for Python and object-oriented programming. https://www.theregister.co.uk/2018/08/07/code_shrew_python/Shrew’d thinking: Code Shrew helps peeps who want to, or need to, gobble a slice of Py
A recently published poll shows that Americans are turning cold on one of the hottest technology frontiers - self-driving cars. A recent study showed that nearly half of drivers now say they’d “never” buy a Level 4 autonomous car, up from 30% two years ago, and Level 2 automation (which is recognised as being risky given the significantly increased cognitive effort it requires) is now the most popular option among those presented. The drop in enthusiasm for self-driving cars is not correlated with awareness of recent accidents involving the technology - but perhaps with a softening in hue of the rose tinted glasses we are using to project AI. http://www.autodealermonthly.com/channel/dps-office/news/story/2018/08/study-autonomous-vehicle-awareness-rising-acceptance-declining.aspxA new study from Cox Automotive shows that consumers now have a deeper understanding of the complexities involved when creating a self-driving car, which is causing them to reconsider their comfort…
At $10,000 for the top end card, NVIDA is clearly aiming these at professional video editing suites, but the addition of built in Tensor Core units aims to speed up end to end editing of film and game graphics - perhaps automating the removal of guide wires from shots, or removing artefacts or entire actual objects from scenes. I just wish the name (“Turing Architecture”) had been saved for a truly self-aware device :) https://techcrunch.com/2018/08/13/nvidias-new-turing-architecture-is-all-about-real-time-ray-tracing-and-ai/In recent days, word about Nvidia’s new Turing architecture started leaking out of the Santa Clara-based company’s headquarters. So it didn’t come as a major surprise that the company today announced…
AI models are complex and take time and compute power to generate - meaning they’re expensive and valuable. IBM has been developing a way to “watermark” deep learning models by embedding specific information in to the model during training such that it’s impossible (or very hard) to remove later, allowing definitive identification of model theft. https://thenextweb.com/artificial-intelligence/2018/07/20/ibm-came-up-with-a-watermark-for-neural-networks/How can you tell if someone stole your AI models? IBM proposes a watermarking technique to protect AI developers and their intellectual property.
In a scary development, China expects to deploy AI powered submarines capable of executing weapon strikes on targets within the next 2-3 years. https://www.artificialintelligence-news.com/2018/07/23/china-sea-power-unmanned-ai-submarines/China is planning to upgrade its naval power with unmanned AI submarines that aim to provide an edge over the fleets of their global counterparts.
Although some are pitching it as “replacing” human call centre workers, a more likely scenario is that mundane or routine interactions can be completely automated, allowing human workers to spend more time on more meaningful, complex or sensitive activities. Yes, this will probably lead to individual call centres hiring fewer people, it could well pan out the same way as ATMs (http://www.aei.org/publication/what-atms-bank-tellers-rise-robots-and-jobs/) - it made the cost of banking cheaper, meaning banks could extend their reach further and open more branches. https://bgr.com/2018/07/24/google-ai-call-centers-focus-of-software/This is the second time in a matter of just a few weeks we’re back writing about how Google is working on artificial intelligence software to replace human call center workers.
Planning how to deploy people and resources (like water and fertiliser) to make the best use of yield is critical to optimising costs in highly volatile industries like wine making. Using drones to survey vineyards (which takes just 15 minutes), and analysing the results using AI, produces faster and more accurate results - the system can even identify grapes which have been too close to bushfires (which would taint the wine with a smokey taste), and can predict with high accuracy when grapes are at their optimal time for harvesting, ensuring that the exact ratio of sugars, mature and just ripe grapes is ready for picking. https://www.opengovasia.com/articles/artificial-intelligence-and-machine-learning-to-improve-australias-winemaking-industryJul 27, 2018 - by Teresa Umali - Winemakers can see in real time which grapes are ready to pick using handheld device that uses near-infrared wavelengths. - opengovasia.com
Although (in theory) any randomly scrambled Rubik’s Cube can be solved in 20-26 moves, current solutions are basically based on brute force searches. Given the massive number of combinations (4.3 × 10^19), one major challenge to training a system is the sparse reward mechanism - DeepMind’s paper outlines the use of a new algorithm - “Autodidactic Iteration” - using 2,000,000 iterations over approximately 8 billion cubes in just 44 hours. https://www.hpcwire.com/2018/07/25/new-deep-learning-algorithm-solves-rubiks-cube/Solving (and attempting to solve) Rubik’s Cube has delighted millions of puzzle lovers since 1974 when the cube was invented by Hungarian sculptor and
Recent advances in AI mean that it would now be possible to develop autonomous weapons - systems which are capable of making automated decisions to take human life. Elon Musk, DeepMind and others have signed a pledge never to create AI weapons:
“We the undersigned agree that the decision to take a human life should never be delegated to a machine. It goes on to warn “lethal autonomous weapons, selecting and engaging targets without human intervention, would be dangerously destabilizing for every country and individual.” https://www.forbes.com/sites/samshead/2018/07/18/elon-musk-deepmind-founders-and-others-promise-not-to-make-lethal-ai-weapons/#165c8a1b7269The signatories have promised to “neither participate in nor support the development, manufacture, trade, or use of lethal autonomous weapons.”
A big step towards making devices like Alexa or Siri (or more likely Google Assistant, given that this research comes from DeepMind) better understand humans is the development of “theory of mind”. By around 4 years old, human children can understand that their beliefs may diverge from those of others, and that understanding that divergence can help predict likely future behaviour of others - applying this to human interaction might make the experience more natural. A first step, DeepMind’s algorithm is able to analyse the behaviour of AI systems which are otherwise too complex for people to understand and to try to predict their behaviour. http://www.sciencemag.org/news/2018/07/computer-programs-can-learn-what-other-programs-are-thinkingAlgorithms achieve a machine theory of mind
Among many promising applications for AI in medicine, cardiology is one with the greatest potential. Current clinical practice calls for manual analysis of a wide range of complex diagnostic imagery, and this analysis is time consuming and error prone, even for the most experienced doctors. Advances in the technology are hampered by ethical concerns that augmenting human decisions with AI violates the relationship between doctor and patient. https://www.news-medical.net/health/Artificial-Intelligence-in-Cardiology.aspxThe continuous development of the technological sector has enabled the industry to merge with medicine in order to create new integrated, reliable, and efficient methods of providing quality health…
In an interesting piece of research intended to highlight the biases embedded in AI systems and training data, a team at the University of Melbourne produced a system capable of making assessments of physical attributes and the emotional state of people in a photo. Hidden in the assessments are a range of biases - gender is assumed to be a binary state, there are only five ethnicities, and emotional judgement or “responsibilities” are clearly highly subjective. https://www.digitaltrends.com/cool-tech/biometric-mirror-judges-your-looks/Would you be freaked out if a facial recognition mirror started making judgments about your age, gender, race, attractiveness, and even trustworthiness? Get ready to meet the Biometric Mirror, a…
Two years after the unveiling of the original Tensor Processing Unit, Google’s announced “Edge TPU” - tiny AI accelerator chips designed to be embedded in IoT devices. Models will be trained on large, server clusters like today, and then embedded in edge devices in factories or workshops - perhaps analysing samples for quality control, processing movement of objects around a plant, etc. https://www.theverge.com/2018/7/26/17616140/google-edge-tpu-on-device-ai-machine-learning-devkitThe hardware is destined for enterprise applications, not your phone
In a major breakthrough, researchers from Deep Mind have improved the accuracy of AI lip reading, with half the error rate of previous methods, and over 50% accuracy. If embedded in to smart devices, it could make lip reading accessible to anyone with a smartphone - both helping the many people who struggle in noisy and crowded environments, and putting at risk the privacy of many others. http://www.sciencemag.org/news/2018/07/lip-reading-artificial-intelligence-could-help-deaf-or-spiesA new algorithm silences its competition
One obvious use case for autonomous cars is to ferry people on the “last mile” between their starting point (e.g. home, office etc.) and public transport, and Google’s Waymo has started a pilot programme in Phoenix to help evaluate the model. https://techcrunch.com/2018/07/31/waymo-partners-with-phoenix-to-connect-people-to-public-transit/Waymo, the former Google self-driving project that spun out to become a business under Alphabet, is launching a program in Phoenix next month that will focus on delivering people to bus stops and…
One of the questions we often ask in interviews is for a candidate to talk about a piece of data they’ve seen recently which surprised or interested them - an interest in data journalism is (for my team) an indicator of a person interested in numbers, a prerequisite for a successful career in data and analytics. These sorts of data are going to become more accessible as Google News starts to include them in search results to help quash “fake news” https://www.engadget.com/2018/08/01/google-search-data-journalism/Google is shining its Search spotlight on useful news data.
Perhaps further evidence that “fitting to a curve” can produce syntactically and mathematically correct prose (e.g. which rhymes, has the correct pace and tone), without truly understanding the meaning of the content that’s being generated, the emotion is missing. I’m sure simulation will continue to improve, but without true understanding of the causal link between words and the emotions they invoke, it’s hard to see how truly creative, emotionally evocative content will ever be generated. https://www.datanami.com/2018/08/01/deep-speare-emulates-the-bard-with-ai/A deep learning model trained on 2,700 of William Shakespeare’s sonnets is giving poetry fans fits trying to tell the AI-generated poems from the real
I’ve never considered before what’s missed when faces are “blurred” to provide anonymity - of course, you lose facial expression and so emotions. A new technique allows faces to be anonymised without losing that expressive motion. https://www.sciencedaily.com/releases/2018/08/180801131551.htmResearchers have devised a way to replace the use of ‘blurring’ faces in news reports when anonymity is needed. The team’s method uses artificial intelligence (AI) techniques that aim to improve…
The Large Hadron Collider generates more data per second than Facebook collects in an entire year - even after compression, it’s far too much to store. Through clever use of AI and machine learning, applied in real time, the data can be analysed almost as it’s generated, and the system decides for itself what dat to keep and what to chuck. More recently, the teams have started deploying deep learning with networks many, many layers deep. But there’s more to come. https://phys.org/news/2018-08-particle-physicists-team-ai-toughest.htmlExperiments at the Large Hadron Collider (LHC), the world’s largest particle accelerator at the European particle physics lab CERN, produce about a million gigabytes of data every second. Even after…
In an interesting piece reminding us that “it’s not their fault, it’s yours” if people can’t follow your user interface to access features they want or could find useful, Fredric Paul argues that, without more and better thought on usability and proper reconsideration of user interfaces for functionality not just to make it “sexy”, IoT “for seniors” will end up no-where, and the potential for devices to help with elder care will never realise their full potential. https://www.networkworld.com/article/3294198/internet-of-things/why-iot-for-seniors-is-a-lot-tougher-than-it-looks.htmlSenior citizens are often touted as a huge potential market for the Internet of Things (IoT), but progress may be slower than a retiree with a bad hip.
We hear a lot about the biases and problems inherent in AI development and use - but this is an interesting approach to solving some societal problems using AI. A piece of software scans news articles and scientific citations to try and identify scientists who are notable but not represented in existing Wikipedia articles, creating draft biographies for human editors to review and publish. So far 40,000 summaries have been produced for both men and women. The article includes a description of the development and training approach taken by the developers. https://www.wired.com/story/using-artificial-intelligence-to-fix-wikipedias-gender-problem/A software program from Primer scours news articles and scientific journals for women scientists who don’t have entries in the online encyclopedia.
The ACLU and nearly 70 other civil rights oranisations have pressed Amazon to stop selling facial recognition technology to governments over fears of misuse. Microsoft has also asked the government to step in and regulate the technology, and others are calling it “the most uniquely dangerous surveillance mechanism ever invented”. https://medium.com/s/story/facial-recognition-is-the-perfect-tool-for-oppression-bc2a08f0fe66It’s easy to accept an outwardly compelling but ultimately illusory view about what the future will look like once the full potential of facial recognition technology is unlocked. From this…
eBay describes 5 key approaches which have helped them drive incremental sales of more than $1 billion per quarter i.e. generating sales which otherwise wouldn’t have happened “quarter after quarter, and year after year”.:
1. deep learning has valuable use cases today
2. there are potential applications right across the business, many invisible to users but with tangible benefits (e.g. “right pricing”, improving advertising, predicting delivery windows)
3. “big data” isn’t new - what’s new is crossing the cost inflection point
Apparently the global market for AI was $2.65 billion, mainly focused on a few core suppliers. The US is the biggest single spender at over 35%, and although text processing was the most common used application in 2017, this is clearly expected to move towards video and other media over the coming years. https://www.techrepublic.com/article/ai-software-market-to-hit-78b-by-2025-here-are-the-top-applications-for-the-technology/The market for AI software is exploding, with IBM and Google leading global suppliers, according to QY Research.
Looking for useful top tip to tune your resume? Dont list your job title, describe your achievements. In particular, what projects did you do? How did data inform the outcome? What skills did you demonstrate that show complexity or breadth? http://uk.businessinsider.com/tips-for-resume-amazon-jobs-2018-7Your résumé is a recruiter’s first impression of you during the job search. To impress recruiters like Celeste Joy Diaz, a recruiting manager at Amazon…
As if to back up concerns that grocery retailers should be scared of Amazon’s entry to the segment, Whole Foods customers are reporting mainly positive improvements since the purchase by Amazon last year, including higher quality merchandise, and of course, the promised lower costs. https://www.512tech.com/technology/survey-says-whole-foods-customers-have-liked-changes-since-amazon-takeover-but-have-they-been-enough/jZVnZbZDCbW07wAqnUdc0I/According to a new survey released by market research firm Morgan Stanley, Whole Foods customers indicated they have had a better overall experience at the grocer since Amazon took over last fall.
A further useful insight from the CNAS report is the list of properties of successful AI adoption which should guide both private as well as state interests:
- possessing large volumes of the right data
- training, enabling and sustaining people with the right (AI) skills
- identify the correct incentives for adoption - including recognition of AI as a general purpose tool
- ensure strong collaboration between public and private actors, including development of appropriate regulatory frameworks (e.g. balance of privacy vs. public interest, or whether distribution of AI-specialised hardware should be controlled like weapons are today) https://www.cnas.org/publications/reports/strategic-competition-in-an-era-of-artificial-intelligenceDeveloping strong, pragmatic and principled national security and defense policies.
In choosing to frame previous industrial revolutions in terms of warfare and the balance of power between state actors (instead of, say, improvements to the lives of individuals, redistribution of wealth to reduce global inequality, or the generation of new forms of capital and “worthwhile” work), the authors are able to articulate a clear set of actions for the US (or any) government who wants to build and cement a technological advantage in to a global projection of power. https://www.cnas.org/publications/reports/strategic-competition-in-an-era-of-artificial-intelligenceDeveloping strong, pragmatic and principled national security and defense policies.
I’m not sure I’d call facebook (media), Amazon (retail, logistics), uber (cabs) etc. technology companies now either. Yes, they are heavily technology-leveraged, but ultimately the machine under the covers matters less than what it achieves. Walmart, like many large companies, is identifying that significant new business opportunities can be released by better leveraging technology. Does that make it a “tech company”? https://www.technologyreview.com/the-download/611674/walmart-wants-us-to-believe-its-turning-into-a-tech-company/Its latest partnerships and new services show the retailer’s continued evolution toward becoming a tech-focused business.
A recent experiment by Facebook pitted humans against AI to see which was better at helping another robot to navigate a (virtual) walk around an area of Hells Kitchen in New York. The bot had to describe its location using natural language (“I can see the bank on the corner”). Although the AI only scored 50% in this mode, when using “symbols” instead, it was able to beat humans 87.08% to 76.74%. The two AI were able to communicate far more efficiently than humans could. But as a test for their new “MASC (Masked Attention for Spatial Convolution)” model, it was a success. https://www.engadget.com/2018/07/11/facebook-improves-ai-by-sending-tourist-bots-to-a-virtual-nyc/Virtual guides help a ’lost’ AI find its way.
Often when prescribing multiple drugs, doctors have very little information to judge side effects or drug interactions, and it can take years for drug side effects to be identified, as their discovery is usually purely by chance. Stanford University researchers trained their system on over 19,000 proteins and their drug interactions, which was able to successfully predict drug interactions based solely on the prescribing combinations. https://newatlas.com/ai-drug-side-effect-prediction-computer-stanford/55426/When a doctor prescribes a patient more than one drug they have no way to predict whether that combination will have an adverse side effect. A new system from Stanford University presents a novel…
There’s a nice breakdown of the usability and scaling challenges the Google Photos team went through with the redesign of their app. Creating a “scrubbable” infinite scrolling page, maximising screen real estate, while maintaining photo aspect ratio, with instant loading and rendering, with libraries of 250,000 photos or more. The compromises and engineering challenges they encountered are laid out with clear explanations. An interesting read. https://medium.com/google-design/google-photos-45b714dfbed1A peek under the hood
Although it was first to market, Siri is so awful that i hardly ever use it. But with the reorganisation to bring Core ML and Siri under the same part of the company within Apple, and with a new “chief of machine learning and AI strategy”, perhaps we’ll see some improvement. https://www.theverge.com/2018/7/11/17559358/apple-new-ai-chief-john-giannandrea-siri-machine-learningJohn Giannandrea is tasked with educating Apple’s assistant
All 4 of the “big players” personal assistants - Apple’s Siri, Google Assistant, Amazon’s Alexa and Microsoft’s Cortana started off female (although they now have male voices). LivePerson CEO, Robert LoCascio, “believes the male-dominated AI industry brings its own unconscious bias to the decision of what gender to make a virtual assistant”. Are the tech giants reflecting biases already present in society? https://www.npr.org/2018/07/09/627266501/the-push-for-a-gender-neutral-siriSiri, Alexa and Cortana all started out as female. Now a group of marketing executives, tech experts and academics are trying to make virtual assistants more egalitarian.
There’s a massive ethical problem here - people expecting medical notes, receipts with personal data, or their emails to only be “read” by a machine may not have given that consent if it was clear a human would read that they ordered takeaway for 2 to their hotel room while on that business trip without their partner. But when i read the Guardian’s article on “fake AI”, i have to say i wasn’t surprised. It reminded me of Andrew Mason’s interview on how he started Groupon (https://mixergy.com/interviews/andrew-mason-groupon-interview/) - the big question was how the business should work, and building technology which may not be usable later was a waste. https://mixergy.com/interviews/andrew-mason-groupon-interview/Using what one expert calls a ‘Wizard of Oz technique’, some companies keep their reliance on humans a secret from investors
TNW has a brief summary of the ways that machine learning is being used to improve authentication and authorization, with a rundown of a number of approaches used by different companies. https://thenextweb.com/artificial-intelligence/2018/07/13/authentication-cybersecurity/To some, the future of authentication might look a little creepy. But the explosion of data and connectivity will provide plenty of ways for AI algorithms to distinguish between imposters and real…
The search for “generalisation” in AI is somewhat hindered by an inability to test for it, so a recent paper by Google’s Deep Mind team provides an interesting insight in to the thought process of teams pursuing this goal. The team generated a number of tests which contain patterns with abstract relationships between elements in the pattern, and between sets of patterns. Within the sets, specific elements are missing, and the researchers found that pattern completion performance was strongly correlated with core model performance. Whether this provides a way to test models remains to be seen and is the subject of further work. https://venturebeat.com/2018/07/11/googles-deepmind-developed-an-iq-test-for-ai-models/In a new paper, researchers at Google subsidiary DeepMind tested the ability of machine learning models to reason abstractly, like humans.
while an interesting use case for sure, i’m not sure that I would pay $1,000 for a dustbin unless it automatically managed the inventory in my kitchen cupboards for me… https://www.digitaltrends.com/home/oscar-ai-trash-can-sorts-recyclables-garbage/Autonomous, an ergonomic office furniture company, announced a Kickstarter campaign for Oscar, a smart home appliance. The AI-based device sorts recyclables and garbage. Environmentally-conscious…
In a very interesting and wide ranging talk on the history (including a very early mechanical perceptron) of AI, Carlos Guestrin outlined 4 trends he sees in the future:
1. shift from parallelism (e.g. spark) to HPC (e.g. deep learning on massive GPU clusters) workloads driving insights from huge (rather than “massive”) data
2. a return to specialized hardware (e.g. custom chips, FPGAs etc. for HPC) and the engineering challenges to fix it (e.g. AutoTVM)
In a couple of short but interesting videos, researchers at Honda show us how they’re designing robots to be tolerant of physical risks, such as knocks, which may cause the robot to topple over and sustain damage to itself or others, by hopping or “running” (several fast steps), depending on the direction of the push. The researchers indicate that future developments might include the ability to switch from vertical to horizontal movement i.e. if you push Asimo too hard it’ll drop to the floor and crawl away. https://spectrum.ieee.org/automaton/robotics/humanoids/asimo-still-improving-its-hopping-and-jogging-skillsHonda is teaching its robots to take longer and faster steps to recover from shoves by transitioning to a running gait, which is exactly what humans do if we need to
I still believe that we have to change the way we’re consuming the earth’s resources if we want to leave to our children anything like the planet we inherited from our parents. But the products like this need to work on the marketing. Who wants to eat algae :) https://spectrum.ieee.org/video/green-tech/conservation/we-grew-algae-and-asked-spectrum-editors-to-taste-itAlgae could be the environmentally-friendly superfood we’ve all been waiting for. But will anyone actually eat it?
It’s interesting to see how Apple and Facebook are approaching the problem of “fake news” differently. Facebook is sticking to it’s “algorithmic” approach, which i guess would be far more scalable if (and it’s a big if) it can be demonstrated to work. Apple’s employing more people to review the news that’s presented through the hardware/software giant’s own apps, teaching us:
1. the scale of the problem facing Facebook’s is simply orders of magnitude larger (Apple only curates content from a chosen set of sources, not any joe schmoe writing a blog), and
I’m skeptical about the true market for bike sharing. I can see the perceived benefits, and when i lived closer in to central London I used to use Boris Bikes more often, i’ve recently tried to rent “dockless” bikes from several of the companies around London and although they never seem to be available nearby when i want them, cities all around the world (e.g. http://theconversation.com/to-end-share-bike-dumping-focus-on-how-to-change-peoples-behaviour-90016) are struggling with how to stop bike “dumping” - the natural “clustering” of bikes at the end of common commuter journeys. https://www.theverge.com/2018/7/2/17526892/lyft-buys-motivate-bike-sharing-expansionThe ride-share company will take on Motivate’s existing contracts, like New York’s Citi Bike
The Very Large Telescope has been used to capture the birth of a planet around a star for the first time. Astronomers have long thought that planets grow through accretion of dust collected around stars - and this series of photographs shows this in action, giving us further evidence of the way our own solar system formed. https://www.npr.org/2018/07/02/625299978/scientists-capture-first-birth-of-a-planetPhotographs of a young planet orbiting a star provide useful information about how planets form and grow.
We are trying to put accessibility at the core of everything we do, and it’s hard - often people see “designing for accessibility” as expensive or time consuming. But it doesn’t have to be. For a start, it’s much cheaper to implement from the beginning than to try to retrofit, and accessible applications are easier for everyone to use, not just those with disabilities or impairments. Most of the pointers in this article are so obvious they shouldn’t have to be stated - but unfortunately many people aren’t even aware of the need to think about them, let alone possessed of the skill to design for accessibility. https://uxdesign.cc/designing-for-accessibility-is-not-that-hard-c04cc4779d94Seven easy-to-implement guidelines to design a more accessible web ❤️
Chinese Tech Titan Alibaba has introduced a new feature to help sellers write compelling and useful copy for adverts with a few clicks of the neural network. Producing millions of suggestions each day, the “AI Copywriter” aims to reduce the “repetitive, low-value work” activities associated with creating multiple formats of an advert for different media. Claiming that the system “allows people to devote more energy to richly creative work”, this will clearly put lower priced (although not necessarily lower skilled) copywriters in a difficult spot, and would concentrate spend on a smaller number of more “elite” copywriters. https://www.alizila.com/alibaba-debuts-ai-copywriter/The technology has passed the Turing test and is capable of producing 20,000 lines of copy in a second, said digital marketing arm Alimama.
Self driving cars always seem to be “tomorrow’s promise”. One major reason is the way that machine learning struggles with “generalising” from more specific data. A child doesn’t need to be shown every possible type of chair to learn what a chair is - but throw a few pixels out and your CNN is likely to miscategorise that wolf as a bear (http://advances.utc.sk/index.php/AEEE/article/download/2202/1271), which could have catastrophic consequences, especially if the knowledge is used maliciously. The Verge is asking whether this limit on capability is leading to a dead end - without significant progress in generalisation driving may be simply too unpredictable to be achieveable https://www.theverge.com/2018/7/3/17530232/self-driving-ai-winter-full-autonomy-waymo-tesla-uberSkeptics say full autonomy could be farther away than the industry admits
This discussion about automation in the luxury goods market (https://www.ft.com/content/dfb9088a-7079-11e8-92d3-6c13e5c92914) reminded me of the chapters in The Man In the High Castle (https://smile.amazon.co.uk/dp/0241246105) where it’s suggested that some hand crafted items are so beautiful that they possess a factor, wu, that makes them desirable, and one of the character’s acquaintances wishes to clone them as “most of the masses still believe in magic”. But cloning the items removes what is intrinsically valuable. To me, automation manufacture of luxury goods seems to follow the same path - removing the skill and artisan nature of their creation threatens the very soul of the items they produce. https://www.ft.com/content/dfb9088a-7079-11e8-92d3-6c13e5c92914Response by European groups to robot revolution is as varied as their runway styles
As AI becomes closer than ever to creating digital artifacts which are indistinguishable from those generated in real life, I’m left wondering how we manage the risks to our understanding of law and justice - think perhaps of a generated “CCTV recording” of a political opponent committing a crime being submitted as evidence in court, and no person nor machine can definitively prove whether it’s fake or genuine. https://techcrunch.com/2018/06/16/facebooks-new-ai-research-is-a-real-eye-opener/There are plenty of ways to manipulate photos to make you look better, remove red eye or lens flare, and so on. But so far the blink has proven a tenacious opponent of good snapshots. That may chan…
I’ve long found the sustainability Oracle’s business model questionable - and their latest move to hide (lack of?) cloud revenue growth in their financials further reinforces my view that they are a company on the way down. https://www.ft.com/content/a4fc61c6-740f-11e8-aa31-31da4279a601Shares slide as analyst worries it may be ‘obfuscating weakness’
We make a lot of use of our Alexa at home, and i’m interested to see how it can help in hotels. Being able to order important but not time-critical services (“alexa, have someone pick up my laundry”), or get information (“alexa, what floor is the gym on”) come to mind. But is it going to be more than a gimmick? I still occasionally visit hotels with those massive Bose speakers with an iPhone 30 pin connector on them. Even when that was the right connector, who ever used them?? I know i just unplugged them to plug my laptop in instead. https://getpocket.com/s/81JtIAmazon has announced a new program designed to help hotels deploy Alexa’s voice-enabled smarts across their properties. Though Amazon’s Alexa-powered Echo speakers are growing in popula…
Humans are good at tasks which require dexterity and manipulation of flexible materials (like thin tubes or fabric), but often these detailed tasks are associated with big, heavy “chunks” of other things (such as wiring up a heavy car dashboard before dropping it in to place). Typically, people and industrial robots are kept separate to avoid catastrophic injuries, but a new class of robot which is “aware” of its working environment and can react accordingly (e.g. slow down when a human moves closer) promises to make robots even more useful, taking control of the heavy lifting and allowing humans to focus on the complex, fiddly work. https://www.technologyreview.com/s/611112/this-company-tames-killer-robotsArtificial intelligence can turn the most dangerous industrial robots into helpful coworkers, and that could transform manufacturing.
Recognising AI as a “general-purpose machine”, rather than a distinct and immediately implementable tool or technique, can help explain why the anticipated gains are not yet being seen. With the introduction of other general-purpose machines, like the electric motor, the computer, the steam engine, it took decades for companies and industries to identify how they needed to change - simply automating an existing business process is unlikely to give massive benefits. Rethinking how an organisation achieves outcomes independent of the existing process or tooling is - but it’ll take many more years to materialize. https://www.technologyreview.com/s/611482/the-productivity-paradoxThe mission of MIT Technology Review is to equip its audiences with the intelligence to understand a world shaped by technology.
Novel new approaches to the use of AI - highlighting its use as an augmentation to human judgement, not a substitute - are welcome, but still fall far short of addressing the elephant in the room - most machine learning or AI today is still pure statistical inference, often without even implicit acknowledgement of the path of causation (grass grows when the sun shines - but which causes which?). Until this problem question is addressed, even the new approaches outlined in this article will just be fitting data to a curve. https://mobile.nytimes.com/2018/06/20/technology/deep-learning-artificial-intelligence.htmlA branch of A.I. called deep learning has transformed computer performance in tasks like vision and speech. But meaning, reasoning and common sense remain elusive.
It’s an often overlooked problem, but although electric vehicles produce zero emissions at point of use, and can be powered entirely with emission free fuel (e.g. renewable power sources), they still contain a lot of rare materials, often mined or produced under somewhat questionable ethical standards, so it’s great to see how the world is starting to respond. https://www.technologyreview.com/the-download/611518/a-freshly-funded-battery-startup-aims-to-ease-the-cobalt-crunchConamix, a little-known startup based in Ithaca, New York, has raised several million dollars to accelerate its development of cobalt-free materials for lithium-ion batteries, the latest sign…
Although i was aware of the benefits of sparsely connected neural networks, this paper outlines an additional, slightly counter-intuitive property - scale-freeness through a method they call “Sparse Evolutionary Training). Starting from a sparse network, the model randomly adds new connections and drops weaker ones, “evolving” in to a more model which is more complex to define, but ultimately simpler, with fewer “hubs” (scale-freeness), and this less densely connected end state is quicker to stabilise (as it requires fewer calculations) and to maintain and train than a traditional statically connected network. https://phys.org/news/2018-06-ai-method-power-artificial-neural.htmlAn international team of scientists from Eindhoven University of Technology, University of Texas at Austin, and University of Derby, has developed a revolutionary method that quadratically…
Uber plans to launch a flying car service (“Uber Elevate”), predicting it’ll be ready around 2025 - progress is being further accelerated by a $20M investment in a dedicated Research and Development site in Paris, Uber’s first technology centre outside the US, focusing on research in to airspace management and overcoming the legal and practical issues this brings up (do you really want hundreds of flying cars zooming over your home?) https://www.thelocal.fr/20180524/uber-to-invest-20-million-to-build-flying-taxis-in-franceRide hailing app Uber wants to build flying taxis in France and announced on Thursday it would invest €20 million to develop the project.
The impact of self-driving cars will be felt far and wide. Aside from the obvious (insurance industry, petrol stations, professional drivers, crash repair centres), CB Insights points out that seemingly disconnected industries - like fast food, real estate, media and healthcare - are also set to be jolted from their comfort zones. Not all of these are negative - if you could watch movies while being shuttled around that’s a boon for those who tell internet access and streaming services. Others are more subtle - how the price of real estate will be affected is as yet unclear (and how will that impact public transport?) https://www.cbinsights.com/research/13-industries-disrupted-driverless-cars/Fast food, real estate, military operations, even home improvement — many large industries will have to shift their strategies in the wake of driverless cars.
A future of truly intelligent machines requires causal reasoning, not simply “nontrivial curve fitting” (the probabilistic association of cause and effect), argues Judea Pearl. Development of true reasoning - why a given action has a certain outcome, not just that they’re correlated - would allow machines to “ask counterfactual questions” - in effect, to predict how a change creates a likely outcome that has never been seen before - and potentially even develop agency and free will. He puts lack of progress in this area down to a missing “calculus for asymmetrical relations” (knowing that the sun causes the grass to grow and not vice versa). https://www.theatlantic.com/technology/archive/2018/05/machine-learning-is-stuck-on-asking-why/560675/?single_page=trueJudea Pearl helped artificial intelligence gain a strong grasp on probability, but laments that it still can’t compute cause and effect.
Although Apple seems to be moving their focus for marketing the Watch towards health conscious consumers, there’s a significant number of people who find wearing the device at work absolutely necessary to stay in touch. Many service industry workers are prohibited from checking phones during the workday or while on shift, but checking a watch is acceptable, allowing them to break the monotony of a quiet afternoon without breaking company policies or seeming inattentive to customers - a scenario I hadn’t previously considered (we didn’t even have smartphones when I was working on a shop floor, and i’m not that old!). https://qz.com/1282210/the-apple-watch-has-found-a-surprisingly-useful-home-in-the-service-industry/If you work on your feet, you know.
I have to admit - Instagram’s switch from chronological to algorithmic content sequencing has left me feeling like i’m missing something if I stop browsing for a minute - but the main culprit for that is bad user interface design (the app instantly swings back to the top of the feed when it relaunches if there’s any new content, meaning you never get to see the older posts), so I’m not convinced that telling people they’re “all caught up” is really going to fix the “compulsive, passive, zombie browsing” they’re worried about. https://techcrunch.com/2018/05/21/scroll-responsibly/Without a chronological feed, it can be tough to tell if you’ve seen all the posts Instagram will show you. That can lead to more of the compulsive, passive, zombie browsing that research sug…
I remember years ago hearing someone describe Google’s biggest rival not as another search engine, but Amazon - people “view Google as a tool to research products, while Amazon is the place they go to buy”. While it seems likely that Google’s Shopping Actions programme will drive business, I do not see how this will break Amazon’s stranglehold on online ordering, and especially not when Google’s apparent long-term target here is to have people order through a voice UI, potentially having never seen the product. I trust Amazon to fix it when things go wrong. If i use this service, who do i go to? Google? The merchant? No-one? https://www.forbes.com/sites/shephyken/2018/05/20/look-out-amazon-here-comes-google/If you look beyond other major online competitors, such as Walmart or Target, who can compete against Amazon? The answer may be … Google.
While I admire Elon Musk’s ability to launch big idea after big idea, I have to agree with Schmidt and Zuckerberg - his concerns about AI stink of moral panic. Yes, we need to have the difficult debates around misuse and fairness, but these debates will only be triggered by continuing to explore the possibilities, not by shutting off the tap. https://www.neowin.net/news/eric-schmidt-thinks-elon-musk-is-exactly-wrong-on-artificial-intelligenceEric Schmidt is the latest person to criticise Elon Musk’s Terminator AI vision. Schmidt said that AI will prove to benefit humanity as populations see ageing populations resulting in fewer workers.
How do you ensure your technically interesting project is truly a force for good, not merely further entrenching existing biases, stereotypes, and social problems? This great set of rules, based on experiences working on AI solutions in low-income countries, can help, regardless of where you’re working:
1. Ask who’s not at the table - are you truly inclusive?
2. Let others check your work - fairness is subjective
3. Doubt your data - does your data suffer from collection bias?
I find it fascinating that there are companies out there large enough, and with specific enough use cases, to justify creating custom hardware to solve their problems. Facebook’s recently confirmed that they’re working on chips dedicated to analyzing live video, to allow them to respond more quickly to unacceptable or inappropriate content (such as suicide or murder being streamed live). Such analysis requires “a huge amount of compute power”, but is certainly an interesting technical, and ethical, challenge. Who helps Facebook determine what content to flag? What happens if it gets it wrong? https://www.bloomberg.com/news/articles/2018-05-25/facebook-is-designing-its-own-chips-to-help-filter-live-videosFacebook Inc. is working on designing computer-chips that are more energy-efficient at analyzing and filtering live video content, its chief artificial intelligence scientist Yann LeCun said.
Further demonstrating that just having the technology isn’t enough - you have to keep innovating to stay relevant - Stitch Fix first started using AI and machine learning back in 2011, and it’s given them a significant “first mover advantage” - but the commoditisation of these capabilities means that the things they once held as their own are now readily available to anyone who can code and who can collect the data. Trunk Club, Amazon Wardrobe and The Chapar are all hot on their tail. https://www.forbes.com/sites/bernardmarr/2018/05/25/stitch-fix-the-amazing-use-case-of-using-artificial-intelligence-in-fashion-retailOnline styling subscription service Stitch Fix uses AI in many aspects of its operation. In collaboration with human stylists, Stitch Fix’s algorithms aim to get relevant fashion into the hands of…
While “replacing 300 CPU-only servers on deep learning training” is hardly a benchmark, 15,500 images per second on ResNet-50 is - just a couple of years ago, training throughput would be 1-2 orders of magnitude slower. Also of interest is the approach that Nvidia is taking here - a single compute “node” will be capable of delivering both AI and HPC workloads with extreme performance (the reference implementation claims two petaflops). https://www.zdnet.com/article/nvidia-unveils-the-hgx-2-a-server-platform-for-hpc-and-ai-workloads/The platform’s unique high-precision computing capabilities are designed for the growing number of applications that combine high-performance computing with AI.
While not the first to develop a virtual world to provide suitable simulations to accelerate reinforcement learning, this world certainly seems to be one of the most complex. It’ll be interesting to see how effective these simulations actually are in the real world; so far though, there are no robots complex enough to actually fully enact what they’ve “learnt”. https://www.digitaltrends.com/cool-tech/virtual-home-robot-chores/The goal of VirtualHome is to help robots learn tasks by first experiencing them in a virtual system. In the current system, an avatar can perform 1,000 separate actions, broken down as subtasks, in…
In further evidence of the “automation increases jobs” argument, Amazon has recently released footage showing how robots in their warehouses make it quicker and easier for “associates” (=people) to pick and pack your order. This increased productivity means that the warehouses with the most robots are the most profitable, and hence employ the most people. The article does not mention whether Amazon’s staff are profiting from this increased productivity the way UPS’ did (https://www.npr.org/sections/money/2014/04/17/303770907/to-increase-productivity-ups-monitors-drivers-every-move) when they massively increased instrumentation on their trucks to achieve a similar level of improved efficiency. https://www.digitaltrends.com/home/amazon-warehouse-tour/If you’re like us, you probably spend a little too much time on Amazon buying stuff you may or may not need. But what happens after you click the “buy” button? How does Amazon get you your stuff so…
In further evidence of the way the reducing cost of technology is saving lives, USGS posted a video showing unmaned drones sent to map and monitor lava flows following the eruption of Kīlauea in Hawaii. Analysis of the drone footage picked up a previously unknown but fast moving flow heading towards an as-yet unevacuated residential area. After notifying the Emergency Operations Centre, it became clear that a resident was stranded in the danger area, and he was instructed to “follow the drone” to safety. In addition to this sort of direct assistance, the drone allowed teams to track lava advancement rates to prioritise further rescue efforts. https://www.facebook.com/USGSVolcanoes/videos/2047215991973618/A USGS UAS mission in Kīlauea volcano’s lower East Rift Zone on May 27, 2018, helps prompt and guide evacuations and leads to the successful rescue of a resident after a lava pond outbreak sent a…
In his (very, very long) book ‘The Rise and Fall of American Growth’ (https://www.amazon.co.uk/dp/0691147728), Robert Gordon lays out an argument that not only is growth slower than than people think, but that the growth spurt from 1870 to 1970 was, by all accounts, a one-off, and growth today is reverting back to the long term mean. Xi Jinping doesn’t buy that, arguing that IOT, blockchain, AI, quantum and mobile computing are poised to drive a new spurt of growth which will exceed even that triggered by the industrial revolution. Only time will tell who’s right. https://www.cnbc.com/2018/05/30/chinese-president-xi-jinping-calls-blockchain-a-breakthrough-technology.htmlChinese President Xi Jinping said in a speech this week that blockchain — the technology underlying bitcoin — has “breakthrough” applications.
What happens when the network for your IOT or connected devices suddenly announces it’s going to make a change which affects millions of devices at your end customers? How do you convince them to upgrade to a product which is essentially the same as the one they currently have without seeming like you’re trying to scam them? An interesting parallel will happen in 2025 as BT Openreach switches off the UK’s analogue phone network, and millions of alarms, traffic lights, and social care devices suddenly lose connection. https://www.ft.com/content/cf0e5816-5a97-11e8-bdb7-f6677d2e1ce8?desktop=true&segmentId=7c8f09b9-9b61-4fbb-9430-9208a9e233c8Plan to retire voice network in 2025 has far-reaching consequences
Probabilistic models of natural language processing don’t seem that revolutionary - after all, humans implicitly work this way - but building a practical but generic framework has been a challenge for engineers and researchers for years (we only have to look at the Alexa Prize (https://developer.amazon.com/alexaprize) to see how hard this issue is). Gamalon’s new product claims to solve this issue. It’ll be interesting to see how it turns out. https://www.technologyreview.com/s/611078/how-uncertainty-could-help-a-machine-hold-a-more-eloquent-conversation/AI startup Gamalon developed a clever new way for chatbots and virtual assistants to converse with us.
Technology can help or hinder. There’s a growing evidence base indicating that overprotective parenting is leading to decreased ability for young adults to manage risk or respond to uncertainty in an inherently chaotic and increasingly fast paced world (and as a result, the pushback against protective playgrounds which sanitise risk is also growing e.g. https://rethinkingchildhood.com/2018/04/19/risk-dangerous-playwork-adventure-conventional-playground/), so I’m interested when I see vendors offer technology which panders to what many consider to be moral panic; overall, I worry that applying technology in this way elevates fears, rather than reducing them. https://www.zdnet.com/article/kt-launches-nb-iot-based-child-monitoring-service/South Korean telco KT has launched a child monitoring service that uses its national NB-IoT network.
I find my Amazon Echo devices useful in a range of situations - getting travel and weather information quickly while i’m trying to get the kids out the door, converting units or setting timers while i’m cooking, playing music while i get on with tasks, even controlling the lights and heating - but i’ve also never ordered anything from it. I’m not sure why - this report asserts that users “don’t trust” the devices with payment info, but Amazon already has all that, so it must be something else. I guess it just feels unusual to order something without even seeing it? http://uk.businessinsider.com/echo-owners-dont-trust-it-enough-to-make-purchases-charts-2018-5When Amazon released the first smart speaker in 2014 and Google released its own two years later, we assumed it was to facilitate purchases through their…
Waymo (Google/Alphabet) is finally launching fully automated vehicles. 52 cars will be deployed around their Mountain View offices and will only be able to operate in and arouund that area. Of note however is a second applicant - China’s JingChi which has requested a licence for a single car with a remote person overseeing the vehicle and able to stop or control it in case of emergency. Waymo assert that their vehicles already operate at SAE-Level 4, which includes automatically stopping in case of system failure (https://dryve.com/glossary/what-are-the-sae-automation-levels/), and so there’s no way for staff remotely monitoring the car to take control of it. https://spectrum.ieee.org/cars-that-think/transportation/self-driving/waymo-filings-give-new-details-on-its-driverless-taxisCalifornia’s DMV has also received an application from the startup JingChi to test fully autonomous vehicles
Recordings of calls between Google Duplex and a hairdresser and restaurant are amazing. The AI interacts just like a human - adding ums and hesitation, and even successfully recovering the conversation when the restaurant staff misunderstood the request. I think this is what most people think of when they imagine a virtual, digital assistant, and I’m certainly looking forward to trying it out. http://www.bbc.co.uk/news/technology-44045424The search giant unveils an experimental tool that can make appointments by calling businesses.
The most likely reason Uber’s self driving car killed a pedestrian is because of settings designed to increase passenger comfort. While I’m sure Uber would agree that in this case they went too far, it reminds us that autonomous vehicles (and robots in general) live only to the moral code we provide them. An interesting side note in this article highlights Dara Khosrowshahi’s vision that Uber is at the centre of the network of autonomous vehicles - rather than designing specific end nodes, Uber expects to work with others to be the one ring to binding them all together. https://www.theinformation.com/articles/uber-finds-deadly-accident-likely-caused-by-software-set-to-ignore-objects-on-roadUber has determined that the likely cause of a fatal collision involving one of its prototype self-driving cars in Arizona in March was a problem with the software that decides how the car should…
Over 10% of all randomised controlled trials in education ever, anywhere in the world, have been funded by the UK government. Following the evidence is hard, especially when it challenges the status quo, common practice, or established “knowledge”, so its good to see the UK government putting this money in to establishing a solid evidence base for effective educational practices. https://www.economist.com/news/britain/21739671-third-its-schools-have-taken-part-randomised-controlled-trials-struggle-getting?frsc=dgA third of its schools have taken part in randomised controlled trials. The struggle is getting teachers to pay attention to the evidence
Why is weather unpredictable? The natural world is governed by thousands of factors, and their relationships are intrinsically chaotic, making them hard to model and so to predict - at least for humans. In most systems the number of variables is so massive that even identifying them is impossible - think about the flickering of the flames of a large bonfire, or how topography affects weather formations. Researchers at the University of Maryland have proven that they can train a machine learning model on the existing time-series data, and the model was able to predict future states approximately 8 times further to the future than a human. https://www.quantamagazine.org/machine-learnings-amazing-ability-to-predict-chaos-20180418/In new computer experiments, artificial-intelligence algorithms can tell the future of chaotic systems.
Stripe’s advances in AI, based on hundreds of billions of data points, have been able to reduce fraud by 25% without materially affecting non-fraud acceptance rates. https://thenextweb.com/artificial-intelligence/2018/04/18/stripes-ai-fraud-detector-crazy-smart/I’m loath to use the term, but Stripe is a revolutionary product. It allows pretty much anyone to accept card payments just by adding a few lines of code to their site, without having to deal with…
A fascinating set of guidelines for making complex work which we typically say “has” to be done face to face (like designing) effective when the team works remotely. I particularly like the emphasis on using a spectrum of tools to support “stepping up” the “bandwidth” of a conversation from asynchronous text (e.g. email, slack) to synchronous, real-time, visual methods (e.g. video chat). Others, such as drop in sessions for constructive feedback on work items, look equally useful, and i look forward to testing some of these out with the team. https://zapier.com/blog/remote-design-culture/More and more companies are seeing the benefits of remote work for productivity in the workplace. As Director of Design at Zapier, I frequently get asked the question of how the design process works…
Choosing an effective loss function is a critical part of training ML models. This thought provoking article reminds us to be critical in the choice of this function, especially as in many models the reward function itself is unclear - does a recommendation system (e.g. promoting new articles, or songs) simply create an echo chamber, or does it broadly converge on the mean? Which of these should score higher? If we penalise the system when users don’t click on articles which violate their confirmation bias - are we acting ethically? http://www.argmin.net/2018/04/16/ethical-rewards/Musings on systems, information, learning, and optimization.
While at first Intel appears to be catching up in the race to develop chips optimised for AI, looking deeper reveals a broader, longer term strategy to develop open code allowing any competing or complimentary framework (Tendorflow, Caffe, MXNet, etc.) to run at optimum efficiency on their hardware. Back to those chips (and the dodgy performance charts) - the authors of this article point out that you get better single chip performance from hardware 3 generations old compared to the newest silicone - although the real measure isn’t single chip, but how to scale out complex models across “farms” of devices, as the big boys (e.g. Facebook) do. https://www.nextplatform.com/2018/04/20/is-open-source-the-ai-nirvana-for-intel/Intel has been making some interesting moves in the community space recently, including free licenses for its compiler suite for educators and open source contributors can now be had, as can rotating…
A practical example of the importance of appearance: “appearing tall … is linked to increased social status across cultures, which researchers hypothesize has an evolutionary origin: If you were a taller caveman, you were probably better at taking down megafauna.” https://www.inverse.com/article/43535-mark-zuckerberg-booster-seat-explanationSitting tall gives him the confidence boost he needs.
1 Managed (durable infrastructure, effective data pipelines, data and model governance)
2 Resilient (automatic alerts when model drift is excessive)
3 Performant (runs in reasonable time on cost effective infrastructure)
4 Measurable (model accuracy, data volume, value released)
5 Continuous (evaluate and retrain models as needed) https://venturebeat.com/2018/04/21/ibm-outlines-the-5-attributes-of-useful-ai/A few weeks ago, a dejected CTO told me it took his team three weeks to build a machine learning model. I told him a model in just three weeks sounded great, and he agreed. So why the long face? Be…
Pouring resources in to Alexa, AWS and experiments like Amazon Go, Amazon invested nearly $23bn on R&D last year, nearly 1/3 of the total spend of the top 5 (next come Alphabet, Intel, Microsoft, and Apple). https://www.recode.net/2018/4/9/17204004/amazon-research-development-rdTech companies claimed the top five spots again this year.
As the cost of AI drops, things which aren’t currently thought to be solvable through prediction will suddenly be viable - and this will primarily be complimented with human judgement. Computers predict better than people can, but then these predictions will be “handed off” to a human to use judgement to determine the response (such as whether or how to act, or to ignore). Ultimately, the authors recommend that companies develop a “thesis” outlining what you plan to “predict” (e.g. what is “best”), the time until AI becomes so embedded that investments without it are not viable, recognising that progress towards that point will be exponential. https://www.mckinsey.com/business-functions/mckinsey-analytics/our-insights/the-economics-of-artificial-intelligenceRotman School of Management professor Ajay Agrawal explains how AI changes the cost of prediction and what this means for business.
The demise of the retail store may have been (greatly) exaggerated. Yes, many big box stores are disappearing, being unable to compete on cost or selection with online vendors, many companies are turning to technology to survive the change by inviting themselves directly in to customers’ homes, or optimising their supply chain and product ranges using AI and small, local, relevant locations. Others are making the retail store the place you go to try out a physical product which you then buy online, creating “showroom destinations” for customers. One thing’s clear - this battle is not yet lost. https://www.cbinsights.com/research/retail-apocalypse-survival-technology-trends/We discuss the technologies and trends, from supply chain software to in-store AR technology, that are helping today’s brick-and-mortar retailers stay competitive as e-commerce continues to grow.
A fascinating tool to support developers. I’m proud to say they had only a few recommendations and findings from my code/repositories (although i have subscribed, so i’ll get notifications for others in future too) - and i can see how a tool like this could really help developers to produce better, more supportable, more secure code. https://techcrunch.com/2018/04/26/deepcode-cleans-your-code-with-the-power-of-aiZurich-based DeepCode claims that their system — essentially a tool for analyzing and improving code — is like Grammarly for programmers. The system, which uses a corpus of 250,000 rule…
An interesting concept - obvious when explained, but of course, many of the good ones are: “While paradigms like imperative or functional programming characterize certain underlying aspects of our mental model of program, gradual programming describes a process by which a mental model is formed” http://willcrichton.net/notes/gradual-programming/Programming is a fundamentally incremental (or gradual) process, and our programming languages should reflect that. I show several ways in which program models transition over time and discuss how…
While IBM’s latest figures show that perhaps the elephant can’t dance after all (https://www.ft.com/content/84dfe694-432f-11e8-93cf-67ac3a6482fd), Microsoft’s pivot from a software to cloud services company is really starting to pay off - reporting revenue nearly $1bn higher than market expectations last year. Changing the direction has clearly been hard (e.g. disbanding the Windows Engineering team, previously the core of the company), and it’s hard to see how a company of that size, and with that number of highly passionate people, can successfully adapt so quickly, but it seems to be well on track. https://www.ft.com/content/6add94ac-49a7-11e8-8ee8-cae73aab7ccbRevenue boost from cloud business and upbeat forecast add to stock price confidence
Construction sites are perfect examples of chaotic environments - a massive number of moving parts, unpredictable environmental conditions, hundreds of people - and there’s a very real risk of injury or even death for every human present. Automation therefore is highly complex, but the first steps are starting to be taken, with robots moving parts and materials to free up humans to work on the more challenging task of actually building. https://www.technologyreview.com/the-download/611005/robots-are-going-to-redefine-japans-skylines/Japanese companies are turning to robots to help build their skyscrapers.
Most power outages are due to failures in the transmission network (storms, broken power lines), not instability in supply. Making the move to newer, cleaner energy solutions is going to be difficult and take time - and cause pain for those involved. But that’s not a good reason to prop up old, dirty, under-utilized coal and nuclear plants with subsidies or tricks. Let the newer “old fuel” plants provide the resilience needed, and replace the even older dirty capacity with newer, cleaner energy. https://www.axios.com/trumps-electricity-solution-in-search-of-a-problem-287efa7b-181f-44a2-85f2-40625e9e22d0.htmlThere’s not a lot of evidence behind his laser focus on coal and nuclear power.
I’d love to have a robot butler. Previous attempts have been hilariously unsuccessful - so i’m not holding my breath - but the goal is certainly worth chasing. https://www.bloomberg.com/news/articles/2018-04-23/amazon-is-said-to-be-working-on-another-big-bet-home-robotsTen years ago, Amazon introduced the Kindle and established the appeal of reading on a digital device. Four years ago, Jeff Bezos and company rolled out the Echo, prompting millions of people to…
Find yourself snowed under with no time to come up with your next big idea? Most of us come back from holidays refreshed and with new goals and objectives - but how do we achieve that level of innovative ideation on a more regular basis? Make time - two hours a week, locked away from distraction, could be enough. This article includes some tips on getting started. https://www.weforum.org/agenda/2017/09/einstein-darwin-and-the-two-hour-genius-ruleZat Rana looks at the trait shared by Einstein, Darwin and Nietzsche - taking the time to pause and think.
“AI is probably the most important thing humanity has ever worked on. I think of it as something more profound than electricity or fire,” Google’s CEO, Sundar Pichai, said at Davos said. “Any time you work with technology, you need to learn to harness the benefits while minimising the downsides.” https://www.weforum.org/agenda/2018/01/google-ceo-ai-will-be-bigger-than-electricity-or-fireThe technology could eliminate many of the constraints we now face, he said.
As more and more services compete for valuable kerb space (deliveries, ride shares, taxis, emergency vehicles), having a common framework, platform, and language to share valuable data on utilisation and timings can help city planners optimise rules and maximise value, ensuring they do this without compromising customer confidentiality (does the city need to know who is getting out in front of the health clinic, or just that it’s a busy place?) https://www.wired.com/story/uber-nacto-data-sharing/https://www.wired.com/story/uber-nacto-data-sharing/?mbid=social_fb&mbid=social_fbThe ride-hailing company is working with DC to share data—and the much coveted curb.
Assembling an Ikea chair in 20 minutes, rather than the 5 that a person takes, doesn’t seem like much of an advance. But while computers excel at trigonometry and logic games like chess, evolution’s billion year head start on interacting with the physical environment means that advances like this are drawing us (very) slowly closer to a world where robots can perform menial but unpredictable physical tasks. https://www.economist.com/news/science-and-technology/21740733-cower-your-silicon-overlords-puny-humans-robots-can-assemble-ikeaCower before your silicon overlords, puny humans
Apple’s new robot, Daisy (an upgraded version of a robot announced in 2016), can disassemble 200 iPhones per hour, sorting the parts for reuse and recycling, extracting parts which traditional recyclers are unable to safely or cost effectively remove. https://www.independent.co.uk/life-style/gadgets-and-tech/news/apple-earth-day-daisy-iphone-recycling-a8312951.htmlApple has created a new robot – not for building products, but for ripping iPhones apart. The robot, named Daisy, can take nine different iPhones models apart and extract the important parts of them,…
The move to paperless movement of goods in these extraordinarily complex logistics chains has the potential to unlock massive benefits, reducing the cost of movements, by shortening the time it takes for goods to cross checkpoints and borders - an example 32 day journey of perishable goods could be completed in 20. https://www.bloomberg.com/news/articles/2018-04-18/drowning-in-a-sea-of-paper-world-s-biggest-ships-seek-a-way-outGlobalization has brought the most advanced trading networks the world has seen, with the biggest, fastest vessels, robot-operated ports and vast computer databases tracking cargoes. But it all still…
I have no idea about the game that the author is engineering manager for, but this is a good write up of a framework for assessing technical debt, including the value of resolving it now vs later (never) https://engineering.riotgames.com/news/taxonomy-tech-debtBill Clark discusses classifying and managing tech debt at Riot.
While I’m sure that eventually, the process could have been automated, anyone who’s tried this even at a trivial scale would tell you to get the process working first, then to automate. So I don’t get how Tesla ended up in this position. https://www.bloomberg.com/news/articles/2018-04-13/musk-tips-his-tesla-cap-to-humans-after-robots-undercut-model-3Tesla Inc.’s Elon Musk, who’s built up an aura around how automated his car assembly plant will be, has good news for humans: We still need your help.
The clothing industry has long relied on low cost labour in developing countries, but advances in industrial robotics and machine learning and vision, at reducing cost, mean even those jobs are now at risk. https://spectrum.ieee.org/robotics/industrial-robots/your-next-tshirt-will-be-made-by-a-robotGeorgia Tech spin-off SoftWear Automation is developing ultrafast sewing robots that could upend the clothing industry
“For the past two decades, it was China who learned more from the US,” he says. “But in the next 10 years, we’ll ride on each other’s successes. There’s no point thinking who will surpass who.” http://www.bbc.co.uk/news/business-43735023The head of China’s ride-hailing giant Didi Chuxing says his team is young, idealistic and full of surprises.
An interesting move from hardware vendor to PaaS provider: The NVIDIA GPU Accelerated Cloud (NGC) for Deep Learning and HPC https://www.nvidia.co.uk/gpu-cloud/A GPU-accelerated cloud platform with access to catalog of fully integrated and optimized containers for deep learning and HPC frameworks. Learn more.
Update 2021-01-08: this is now out of date. See my updated post with a much easier method.
I have a number of Ubiquiti UAPs, and I manage them with the UniFi app, installed on a linode server. Like any publicly hosted server, i want to use a trusted SSL certificate, and for that, I chose LetsEncrypt with DNS-01 validation, as i found a useful helper script by thatsamguy on the UniFi forums. I use AWS Route53 to host the DNS zone.
Some of my docker containers were complaining that they didn’t have enough drive space. This looked odd - so i logged in to the host and checked around:
checked it’s running with the docker ps -a command: robert@ubd:/mnt$ sudo docker ps -a CONTAINER ID IMAGE COMMAND CREATED STATUS PORTS NAMES f33434ebccaf mnbf9rca/cups-google-print “/sbin/my_init” 2 minutes ago Up 2 minutes cups-google-print
Browsed to https://<server IP>:631/ to see that it’s running
I purchased an IBM M1015 to use as an HBA in my server. As part of that, I wanted to flash it with the IT firmware, however, I was getting errors, even when I used the original IBM firmware from their website (my mirror copy):
C:\> megarec -cleanflash 0 M1000FW.ROM

MegaRAID HWR Controller Recovery tool. Version 01.01-004 February 05, 2010
Copyright (c) 2006-2008 LSI Corp.
Supports 1079 controller and its Successors


Erasing Flash Chip (8MB)....
 Completed: 100%
Flashing Image. Please wait...


Currently flashing component = BIOS
Programming Flash....
 Completed: 100%
Verifying the Flashed Data...


Currently flashing component = HIIM
Programming Flash....
 Completed: 100%
Verifying the Flashed Data...


Currently flashing component = APP
Error in downloading the image.
Error code = 64
Failed to flash the image. Please retry recovery
I’d never seen an M1015 before, at least not close up. Closer inspection of the card, however, revealed a code: FRU 46C8927. I know FRU" means “Field Replaceable Unit” i.e. something you can order as a replacement part. So I googled that code, and discovered that this was an IBM M5015, not an M1015. The M5015 cannot be used in IT mode, so I had to send it back.
First things first - you do this at your own risk. I take no responsibility for anything going wrong - and it can go wrong. If you are in doubt - don’t do it. And if it goes wrong - don’t blame me…
Download the firwmare files from here: sas2008 (see footnote for original source)
Extract the files and place them on the root of the USB stick.
Download the latest LSI firmware from the Avago site. You’re looking for Firmware for an SAS 9211-8i Host Bus Adaptor. At the time of writing, this is version P20.
Extract the LSI firmware to a folder on your machine.
Create a subfolder on the USB called P20
From the extracted LSI firmware, copy the following to the P20 folder on the USB:
The 2118it.bin file from <zip>\\firmware\\HBA_9211_8i_IT folder
mptsas2.rom from sasbios_rel folder
sas2flsh.exe from sas2flash_dos_rel folder
Look at the back of the card and note down the SAS address - it’s something like 500605B0xxxxxxxx.
put the card in the machine, and switch it on.
Boot to the USB stick - press F11 during POST and select USB.
Flash the firmware:
Type the following: megarec -writesbr 0 sbrempty.bin megarec -cleanflash 0
Type the following: megarec -writesbr 0 sbrempty.bin megarec -cleanflash 0
Reboot, again booting from the USB stick
Next, install the P10 or P11 firmware - type the following: sas2flsh -o -f 2118it.bin -b mptsas2.rom sas2flsh -o -sasadd 500605bxxxxxxxxx (x= numbers for SAS address)
Reboot, again booting from the USB stick
Finally, upgrade to the P20 firmware - type the following to change to the folder and execute flash of the new firmware: cd p20 sas2flsh -o -f 2118it.bin -b mptsas2.rom
Remove the USB stick
Reboot.
Some people recommend to disable loading the Option ROM. On my machine, loading the option room caused an NMI, so i ignored it, but if you want to do it: Load the Option ROM (press CTRL-C on boot) and set “Boot Support” to “Disabled”
The original instructions for this task are here, with my additions to update to the P20 firmware - I’ve archived them here for my own reference.
This post is the second in my series describing how i migrated from Unraid to Napp-It, and describes how I prepared for migration.
So - preparing for migration…
First, i wanted to capture the docker configuration for each of my existing containers. To do this, I forced the container to update, then when unraid presented me with the “success” screen, I captured the docker run command, like this (which captures the RUN command for my CUPS container with Google Print extensions): root@localhost:# /usr/local/emhttp/plugins/dynamix.docker.manager/scripts/docker run -d –name=“cups-google-print” –net=“host” –privileged=“true” -e TZ=“UTC” -e HOST_OS=“unRAID” -e “CUPS_USER_ADMIN”=“admin” -e “CUPS_USER_PASSWORD”=“pass” -e “TCP_PORT_631”=“631” -v “/mnt/user/appdata/cups-google-print”:"/config":rw -v /dev:/dev -v /etc/avahi/services:/avahi -v /var/run/dbus:/var/run/dbus mnbf9rca/cups-google-print
During the process of installing VMWare on to my Gen8 Microserver, I had trouble writing data to the internal SD card - in fact, I couldn’t even see it. Looking in the ILO Event Logs I saw this:
Embedded Flash/SD-CARD: Embedded media manager failed initialization.
googling this didn’t get me much - just forum posts with people complaining about it, but then i found this HPE Customer Advisory, which lists out the steps needed to reset the error. Basically:
I’ve been a user of Unraid since 2012, when I had to find a solution to my home storage after Windows Home Server was abandoned by Microsoft. Unraid has been very good for me, and the introduction of a Docker engine with Unraid 6 was very welcome. That said, I’ve recently encountered issues with bitrot, and the fact that unraid can’t use ZFS as the disk format annoys me. LimeTech claim that their parity check process should detect bitrot - however, something doesn’t seem to be working, as using using the Dynamix File Integrity plugin i can see it happening. In any case, knowing it’s happened isnt the same as being able to correct it, which just isn’t possible on Unraid without using BTRFS but many people simply don’t trust BTRFS, and besides, I fancy a change. So - over to VMWare EXSi and ZFS on Napp-It.
When installing Webmin, I’ve sometimes come across an error installing a dependency package, apt-show-versions:
Setting up apt-show-versions (0.22.7) ...
** initializing cache. This may take a while **
FATAL -> Failed to fork.
dpkg: error processing package apt-show-versions (--configure):
subprocess installed post-installation script returned error exit status 100
dpkg: dependency problems prevent configuration of webmin:FATAL -> Failed to fork.
This is caused by the fact that apt-show-versions can’t read compressed index files. Thankfully, the solution is quite simple:
As I’ve been playing around with Azure Functions I’ve slowly outgrown the web-based editor. It’s not that it’s not useful, it’s just that I miss intellisense (I’ll come back to this in a later post), and I accidentally deployed a change which broke one of my functions. I’d made dozens of tiny changes, but I simply could not figure out which one it was. Not having a version history, I was kinda screwed.
I accidentally deployed a dodgy bit of code to one of my function apps. Then, even when I tried to revert to a “known good” version of my code via the GUI, it still didn’t work. No matter what I did, I kept getting the dreaded “Compilation Failed” error - but there was no more information. No useful compilation errors…
2016-10-23T20:35:46.853 Function started (Id=5ededb27-6144-40d1-8d14-8db77d70b771)
2016-10-23T20:35:47.901 Function compilation error
2016-10-23T20:35:47.901 Function completed (Failure, Id=5ededb27-6144-40d1-8d14-8db77d70b771)
2016-10-23T20:35:48.369 Exception while executing function: Functions.fetchDepartureBoardOrchestrator. Microsoft.Azure.WebJobs.Script: Script compilation failed.
It was so frustrating. Until I worked out that you can actually restart the power app host - just go to the Function App Settings then click “Go To App Service Settings” at the bottom. You’ll see the traditional “full” properties and settings blade, and at the top is a “Restart” button. Then I was able to save my updated code.
I’ve been playing around with my Nextion and a Particle Photon for a while. The idea is to pull data from a variety of services and have it available on a display by the front door - things like the weather, the outside temperature (from my Netatmo), and the next 3 trains to Seven Sisters from our station. Living, as we do, at the end of the Enfield Town branch line, it can be a bit hit and miss as to whether or not you make the train, or if it’s even running.
While trying to install the C# scripting package Microsoft.CodeAnalysis.CSharp.Scripting from nuget, but was getting odd messages about missing dependencies. I spent ages trying to figure it out as all the dependency versions appeared to match (e.g.
Unable to find a version of 'Microsoft.CodeAnalysis.Common' that is compatible with 'Microsoft.CodeAnalysis.CSharp 2.0.0 constraint: Microsoft.CodeAnalysis.Common (= 2.0.0)', 'Microsoft.CodeAnalysis.Scripting.Common 2.0.0 constraint: Microsoft.CodeAnalysis.Common (= 2.0.0)'
however, eventually I discovered that you neeed .NET 4.6. Doh!
I started writing EnfieldTownBot using Azure Logic Apps. It’s pretty easy, but i soon hit a challenge - it’s so expensive! My app was pretty simple - a trigger, a “for…each”, a condition and a http callout to my Twitter Poster Function App:
So - if there are no delays, that’s (recurrence + httprequest + foreach + 3 x (condition)) = 6 actions. There could be up to 9 if the postToTwitter action also triggers. I want to run this function 2x (once for trains FROM Enfield Town, once for trains TO Enfield Town), so that’s 12-18 actions per request. And I want to run it every 15-30 seconds to get the latest information published ASAP. So that’s 48-72 actions per minute. Over a day, that’s 69,120 to 103,680 actions. Over a (31 day) month, that’s 2,142,720 to 3,214,080 actions. Taking a mean of these (2,678,400), and looking at the current pricing, it would cost me £450 a month to run this app. Wow. I don’t care about late trains THAT much…
After my last post, I spent some time looking through this. Eventually, I found a really lightweight class which does what i need.
After spending some time adding some error handling to the api.request() method, I then wrapped a webrequest around it and created a function app. You can find it here: https://github.com/mnbf9rca/TwitterFunctionApp
Earlier this year, we got a new car, a BMW 3 series. It came subscribed to the BMW ConnectedDrive service, and that comes with an iPhone or Android app. So, of course, I immediately set about deconstructing the traffic to figure out what was going on, inspired by the work of Terence Eden. Unfortunately, BMW appears to have implemented certificate pinning in the time since Terrence wrote his paper, so my favourite tool, Charles Proxy, was useless - the BMW app simply dropped the connection.
I have to say that the twitter API documentation is absolutely abysmal. It’s impossible to navigate - calls make reference to other calls but the major problem is that there are almost no examples - they almost all recommend that you use a library. So how on earth are you supposed to learn how the API works? How do you write a bot which tweets as itself (such as my https://twitter.com/EnfieldTownBot)?
When we bought our house a few years ago, we totally gutted it and one of the things we installed was an evohome heating system. Honeywell has an iphone app for the evohome, so recently, I decided to explore the API. Unfortunately, Honeywell doesn’t seem to offer a public API, so I spent a bit of time deconstructing the app with the help of the excellent Charles Proxy.